
Cost per section in a LangChain release-post agent
A planner, a parallel section writer, an editor and a summarizer in LangChain 1.x on Claude, then a blocking budget on the role that fans out.
- Framework
- LangChain 1.x
- Provider
- anthropic
- Python
- 3.11+
- Capsera
- pip install capsera
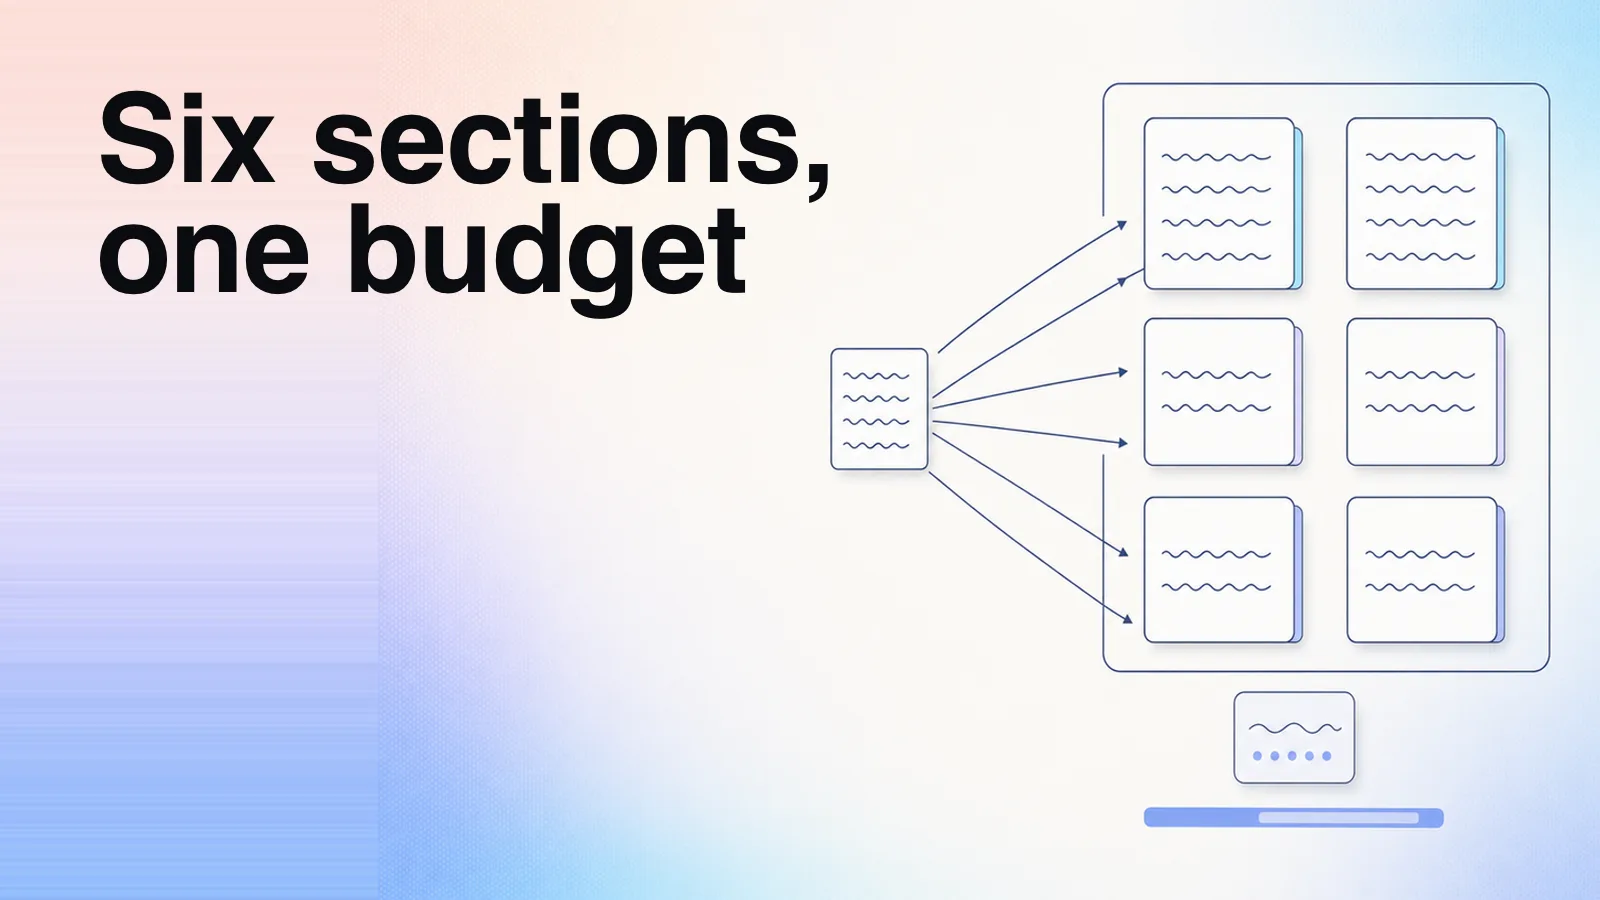
This builds a release-post agent in LangChain 1.x against Claude: a planner turns
a brief and a set of internal notes into sections, a writer drafts every section
in parallel, an editor reads the assembled draft for problems that cross section
boundaries, and a summarizer writes the title and standfirst. One brief is four
model calls at the floor and thirteen at the cap, and the role that decides where
in that range a run lands is also the most expensive one. The last third of this
page adds Capsera: one init() call to capture every request, four decorator
lines to say which role made it, and a blocking budget on the role that
multiplies.
What you will build
draft.py, a single-file agent with four roles and a supervisor:
- planner — one call on the cheap model. Reads the brief and a one-line index of the source notes, returns sections with a heading, the source ids each one may use, and what it has to establish.
- writer — one call per section, run in parallel, on the stronger model. Writes the section body from the assigned sources only, with a source id on every factual sentence. The multiplier.
- editor — one call. Reads the assembled draft and reports what crosses sections: a fact explained twice, two sections that disagree, a measurement stated more broadly than its source allows.
- summarizer — one call. Writes the title and the standfirst from the finished draft, which is the one piece of text that has to see all of it.
Assembly, the embargo check and the citation check are not model calls. Stitching
sections into a document is a join, and checking which source ids a section
cited is a regex against a set. A content agent that spends a model call on
either has a cost curve nothing in the prompts explains.
Each role is its own function. That matters later — it is the seam the instrumentation attaches to — and it is the better shape regardless, because a pipeline that inlines four model calls has nothing you can name, budget, or move to a different model.
Written against LangChain 1.x with langchain-anthropic, calling Anthropic's API
directly rather than through a gateway. Models: claude-haiku-5-5 for the
planner, the editor and the summarizer; claude-sonnet-5-5 for the writer.
Prerequisites
Python 3.11 or newer.
pip install "langchain>=1.0,<2" langchain-anthropic
The major is pinned so this page stays true as LangChain moves.
langchain-anthropic is left unpinned on purpose: install the one that matches
your langchain major.
You need an Anthropic API key. ChatAnthropic reads ANTHROPIC_API_KEY from the
environment, so export it and no code has to touch it:
export ANTHROPIC_API_KEY=...
Step 1 — Fix the source material, and decide what may be published
A content agent is only as honest as the material it is allowed to see. Start there. The fixture below is six internal notes for a release of a fictional job scheduler, and it is built around the things that make release posts go wrong rather than the things that make them easy: a breaking change that lives in a different note from the change that caused it, a measurement whose source explicitly bounds it, and a roadmap draft nobody has agreed to ship.
"""draft.py — the source material a release-post agent may write from."""
import re
from dataclasses import dataclass

SOURCES = {
    "changelog-2026-10": (
        "Scheduler 4.2. Inline retries removed from the worker loop. Failed "
        "jobs now move to a retry queue with exponential backoff. Dead letters "
        "are kept for seven days. The worker.retry_attempts config key is "
        "renamed queue.max_attempts and the old key is ignored."
    ),
    "design-note-retry-queue": (
        "A retry inside the worker loop holds the slot while it waits, so one "
        "slow dependency drains the pool. Moving retries to a queue frees the "
        "slot immediately. The trade we accepted: jobs for one tenant are no "
        "longer guaranteed to run in submission order once any of them has "
        "been retried."
    ),
    "support-thread-8831": (
        "Customer writes: every few days our queue depth climbs for about an "
        "hour and nothing in the dashboard explains it. We eventually find one "
        "endpoint timing out and everything else stuck behind it."
    ),
    "migration-steps": (
        "Before upgrading, rename worker.retry_attempts to queue.max_attempts "
        "in your config. A deploy that keeps the old key starts with the "
        "default of three attempts and logs a warning once. Inspecting dead "
        "letters needs the new queues:read scope on the API token."
    ),
    "benchmark-note-1004": (
        "Replaying one tenant's October 4 traffic against 4.2, p99 job latency "
        "fell and the worker pool never saturated. Measured on one tenant's "
        "replay on staging hardware. Not a general performance claim and not "
        "to be written as one."
    ),
    "roadmap-draft-q4": (
        "NOT FOR PUBLICATION. Draft plans for per-tenant queue priorities and "
        "a managed dead-letter replay screen. Neither is committed and neither "
        "has a date."
    ),
}

EMBARGOED = frozenset({"roadmap-draft-q4"})
PUBLISHABLE = [sid for sid in SOURCES if sid not in EMBARGOED]

BRIEF = (
    "Write the release post for Scheduler 4.2, for operators who run the "
    "service themselves. They need to know what changed, what it means for "
    "the way their jobs behave, and what they must do before upgrading."
)

_BULLET = re.compile(r"^\s*(?:[-*•]|\d+[.)])\s*")
_CITATION = re.compile(r"\[([a-z0-9\-:]+)\]")


@dataclass
class Section:
    heading: str
    sources: list[str]
    angle: str


def source_index() -> str:
    return "\n".join(
        f"{sid}: {' '.join(SOURCES[sid].split()[:12])}..." for sid in PUBLISHABLE
    )


def source_notes(source_ids: list[str]) -> str:
    return "\n\n".join(f"[{sid}]\n{SOURCES[sid]}" for sid in source_ids)


def _lines(text: str, limit: int) -> list[str]:
    cleaned = (_BULLET.sub("", line).strip() for line in text.splitlines())
    return [line for line in cleaned if line][:limit]


def assemble(sections: list[Section], drafts: list[str]) -> str:
    return "\n\n".join(
        f"## {section.heading}\n\n{body.strip()}"
        for section, body in zip(sections, drafts, strict=True)
        if body.strip()
    )


def off_source(body: str, allowed: list[str]) -> list[str]:
    return sorted(set(_CITATION.findall(body)) - set(allowed))


def leaked(body: str) -> list[str]:
    return sorted(set(_CITATION.findall(body)) & EMBARGOED)


if __name__ == "__main__":
    print(source_index())
PUBLISHABLE is the load-bearing line. The embargoed note is filtered out of the
index the planner sees and is therefore never assigned to a section, so its text
never enters a prompt at all. That is the control; leaked() is only the
backstop, and it is worth being exact about what it can and cannot catch. It
matches a cited id, so it catches a planner that invented
roadmap-draft-q4 from the brief and a writer that echoed it. It cannot catch a
paraphrase of something nobody put in the prompt, because there is nothing to
paraphrase. Keeping the material out is the mechanism. The regex is the receipt.
off_source is the same idea one level down. Each section is given a subset of
the notes, and a citation outside that subset means the writer referred to
something it was not shown — usually a plausible id it pattern-matched from the
index. Set membership catches it for free, and nothing else will.
assemble drops empty bodies rather than rendering an empty ## heading. That
is pure tidiness today. It becomes the degrade path once a budget is involved.
Step 2 — Plan the post as sections, not as an outline
The planner's job is not to write an outline a human would approve. It is to produce a structure the rest of the program can execute: a heading to key on, a source list to constrain the prompt, and one sentence of intent.
# fragment
from langchain_anthropic import ChatAnthropic
from langchain_core.output_parsers import StrOutputParser
from langchain_core.prompts import ChatPromptTemplate

FAST_MODEL = "claude-haiku-5-5"
MAX_SECTIONS = 6

PLAN_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You plan a release post as a list of sections. One section per "
            "line, in this exact form:\n"
            "heading :: source-id,source-id :: what this section must establish"
            "\nNo numbering, no commentary, no blank lines. Use only source ids "
            "from the index you are given. A section names every source it "
            "needs and none it does not. Give the breaking change and the steps "
            "before upgrading their own section rather than a paragraph inside "
            "another one. At most {max_sections} sections.",
        ),
        ("human", "Brief:\n{brief}\n\nSource index:\n{index}"),
    ]
)

planner_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)
plan_chain = PLAN_PROMPT | planner_llm | StrOutputParser()


def plan(brief: str) -> list[Section]:
    raw = plan_chain.invoke(
        {"brief": brief, "index": source_index(), "max_sections": MAX_SECTIONS}
    )
    sections: list[Section] = []
    seen: set[str] = set()
    for line in _lines(raw, MAX_SECTIONS):
        parts = [part.strip() for part in line.split("::")]
        if len(parts) != 3 or not parts[0] or parts[0] in seen:
            continue
        allowed = [sid for sid in parts[1].split(",") if sid.strip() in PUBLISHABLE]
        if not allowed:
            continue
        seen.add(parts[0])
        sections.append(
            Section(heading=parts[0], sources=[sid.strip() for sid in allowed], angle=parts[2])
        )
    return sections
Lines with a separator rather than JSON. A line the model malformed is one section skipped; a malformed JSON array is an exception, and a retry on a parse failure is a call you pay for twice. The three fields are positional on purpose — the heading first, because everything downstream keys on it.
The source ids are filtered against PUBLISHABLE, not merely checked. A planner
that writes queue-metrics because the brief implied one should exist does not
get a section built on an id that will KeyError in source_notes, and a
planner that reaches for the embargoed note gets it dropped before the writer is
ever asked to use it.
Headings are deduplicated because the heading is the join key. It is what the editor names when it sends a section back, and what the supervisor uses to put the rewritten body in the right slot. Two sections called What changed means one of them silently receives the other's revision.
The cap lives in Python. A model asked for at most six sections will occasionally
write eight, and the slice in _lines is what makes that harmless — not for
tidiness, but because each extra section is a full call on the expensive model.
Step 3 — Write every section in parallel
This is the role a reader actually reads, and the only one on the stronger model. It is also the one that runs more than once.
# fragment
WRITE_MODEL = "claude-sonnet-5-5"
WRITE_CONCURRENCY = 3
SECTION_WORDS = 130

WRITE_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You write one section of a release post for operators who run the "
            "service themselves. Around {words} words. Every sentence that "
            "states a fact ends with the id of the source it came from, in "
            "square brackets. Write from the sources below and from nothing "
            "else: if they do not support a claim, leave it out. Never state a "
            "measurement more broadly than the conditions its source gives. No "
            "heading, no preamble, no sign-off — the body of the section only. "
            "Apply the revision note exactly and change nothing else.",
        ),
        (
            "human",
            "Section heading: {heading}\nThis section must establish: {angle}\n\n"
            "Sources:\n{sources}\n\nRevision note:\n{note}",
        ),
    ]
)

writer_llm = ChatAnthropic(model=WRITE_MODEL, max_tokens=700, temperature=0)
write_chain = WRITE_PROMPT | writer_llm | StrOutputParser()


def write_sections(sections: list[Section], notes: dict[str, str]) -> list[str]:
    return write_chain.batch(
        [
            {
                "heading": section.heading,
                "angle": section.angle,
                "sources": source_notes(section.sources),
                "note": notes.get(section.heading, "none"),
                "words": SECTION_WORDS,
            }
            for section in sections
        ],
        config={"max_concurrency": WRITE_CONCURRENCY},
    )
One section per call, not the whole post per call. A single call that writes every section is cheaper and it costs you the two things this shape exists for: each section's prompt would have to carry every source rather than its own, and a revision would rewrite the whole post to fix one paragraph. Per-section calls keep the prompt proportional to the section and make a rewrite cost one section.
The revision note is a field in the same prompt rather than a second prompt. The
first pass sends none, a rewrite sends the editor's line. Two prompts that
differ by one field are two prompts to keep in step, and they drift.
"Never state a measurement more broadly than the conditions its source gives" is
aimed at benchmark-note-1004, and it is the sentence that keeps this agent
publishable. The note says p99 fell on one tenant's replay on staging. A writer
asked for a release post will reach for faster for everyone, which is a claim
nobody measured, in a document with the company's name on it. The source bounds
itself; the prompt has to say that the bound travels.
max_concurrency bounds how many sections are in flight. Six sequential calls on
the stronger model is six round trips for work where no section depends on
another. It is also, as the budget section gets to, the number that decides how
far a cap can overshoot.
Step 4 — Edit what the sections cannot see
Every writer call sees one section's sources and nothing else, which is what keeps the prompts small — and it means no writer can see repetition, a contradiction, or a breaking change explained in one section and left without its migration step in another. Those are exactly the faults a draft stitched from parallel calls has.
# fragment
MAX_FIXES = 3

EDIT_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You edit a post whose sections were written separately and could "
            "not see each other. Report only faults that cross sections or "
            "misstate a source: the same fact explained twice, two sections "
            "that disagree, a measurement stated more broadly than its source "
            "allows, a change that needs a migration step the post never "
            "gives. Reply with the single word CLEAN, or one line per section "
            "to fix, in this exact form:\n"
            "heading :: what to change\n"
            "At most {max_fixes} lines, worst first. Never rewrite the text "
            "yourself.",
        ),
        ("human", "Brief:\n{brief}\n\nDraft:\n{draft}"),
    ]
)

editor_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)
edit_chain = EDIT_PROMPT | editor_llm | StrOutputParser()


def review(brief: str, sections: list[Section], drafts: list[str]) -> dict[str, str]:
    raw = edit_chain.invoke(
        {
            "brief": brief,
            "draft": assemble(sections, drafts),
            "max_fixes": MAX_FIXES,
        }
    )
    if raw.strip().upper().startswith("CLEAN"):
        return {}
    headings = {section.heading for section in sections}
    fixes: dict[str, str] = {}
    for line in _lines(raw, MAX_FIXES):
        heading, _, note = line.partition("::")
        if heading.strip() in headings and note.strip():
            fixes[heading.strip()] = note.strip()
    return fixes
The editor is asked for instructions, not for prose. An editor that rewrites
returns a whole post you then have to diff against the one you had, on a cheap
model you deliberately did not pick for writing. An editor that returns
heading :: what to change returns work the writer can do, scoped to the
sections that need it — which is why the rewrite costs two calls instead of six.
MAX_FIXES is a cost bound, not a quality setting. Every line the editor returns
is a call on the expensive model, so the cap on what it may report is the cap on
what a review round can cost. Three is defensible because the faults are ranked
worst first and a draft with more than three cross-section problems usually has a
planning problem, not a writing one.
Unknown headings are dropped. The editor is quoting a heading back, and a model quoting a string will occasionally normalise its capitalisation or trim a word. A fix keyed to a heading no section has would otherwise rewrite nothing while looking like it did something.
Step 5 — Title the post last
The title and the standfirst are the only text that has to be true of the whole document, so they are written from the finished draft rather than from the brief. It costs one cheap call and it is the difference between a title that describes the post and a title that describes the intention.
# fragment
TITLE_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You write the title and the one-sentence standfirst for the post "
            "you are given. Exactly two lines: the title first, the standfirst "
            "second. The title is a plain statement of what changed, under "
            "sixty characters, no colon and no wordplay. The standfirst says "
            "who has to do something before upgrading and what it is. Add "
            "nothing else.",
        ),
        ("human", "{draft}"),
    ]
)

summarizer_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=192, temperature=0)
title_chain = TITLE_PROMPT | summarizer_llm | StrOutputParser()


def headline(post: str) -> tuple[str, str]:
    lines = _lines(title_chain.invoke({"draft": post}), 2)
    if not lines:
        return ("", "")
    return (lines[0], lines[1] if len(lines) > 1 else "")
The fallback returns empty strings rather than inventing a title. A content agent that fabricates a headline when the call came back unusable produces the one failure nobody checks, because a post with a title looks finished.
Step 6 — The supervisor
One function, and every branch the agent can take is visible in it.
# fragment
from typing import Any

MAX_ROUNDS = 1


def write_post(brief: str) -> dict[str, Any]:
    sections = plan(brief)
    if not sections:
        return {"post": None, "reason": "the planner produced no usable sections"}

    drafts = write_sections(sections, {})
    fixes = review(brief, sections, drafts)
    rounds = 0
    while fixes and rounds < MAX_ROUNDS:
        targets = [s for s in sections if s.heading in fixes]
        rewritten = write_sections(targets, fixes)
        by_heading = dict(zip([s.heading for s in targets], rewritten, strict=True))
        drafts = [
            by_heading.get(s.heading, body)
            for s, body in zip(sections, drafts, strict=True)
        ]
        rounds += 1
        fixes = review(brief, sections, drafts)

    post = assemble(sections, drafts)
    title, standfirst = headline(post)
    return {
        "post": post,
        "title": title,
        "standfirst": standfirst,
        "reason": None,
        "sections": [s.heading for s in sections],
        "rounds": rounds,
        "unresolved": sorted(fixes),
        "off_source": sorted(
            {
                sid
                for s, body in zip(sections, drafts, strict=True)
                for sid in off_source(body, s.sources)
            }
        ),
        "leaked": sorted({sid for body in drafts for sid in leaked(body)}),
    }
MAX_ROUNDS bounds the obvious loop. Write, review, rewrite, review has no
natural end — an editor can always find one more thing — and every lap costs up to
MAX_FIXES calls on the expensive model plus a review. One round is a defensible
default because a second rarely changes the verdict: a cross-section fault that
survived a targeted rewrite is usually a planning fault, and rewriting the same
section again does not fix how the post was divided.
The final fixes is returned rather than swallowed. A run that used its round and
still has notes produces a post, with the headings the editor would not pass
travelling alongside it. That is the honest shape: the caller decides whether to
publish, not the agent that wrote it.
Count the calls: one planner, one to six writers, one editor, up to three rewrites, one more editor if anything was rewritten, one summarizer. Four at the floor and thirteen at the cap. Both numbers come from your constants; nothing in your file decides where between them a given brief lands.
The whole file
"""draft.py — a release-post agent: plan, write, edit, title."""
import re
from dataclasses import dataclass
from typing import Any

from langchain_anthropic import ChatAnthropic
from langchain_core.output_parsers import StrOutputParser
from langchain_core.prompts import ChatPromptTemplate

FAST_MODEL = "claude-haiku-5-5"
WRITE_MODEL = "claude-sonnet-5-5"

MAX_SECTIONS = 6
WRITE_CONCURRENCY = 3
SECTION_WORDS = 130
MAX_FIXES = 3
MAX_ROUNDS = 1

SOURCES = {
    "changelog-2026-10": (
        "Scheduler 4.2. Inline retries removed from the worker loop. Failed "
        "jobs now move to a retry queue with exponential backoff. Dead letters "
        "are kept for seven days. The worker.retry_attempts config key is "
        "renamed queue.max_attempts and the old key is ignored."
    ),
    "design-note-retry-queue": (
        "A retry inside the worker loop holds the slot while it waits, so one "
        "slow dependency drains the pool. Moving retries to a queue frees the "
        "slot immediately. The trade we accepted: jobs for one tenant are no "
        "longer guaranteed to run in submission order once any of them has "
        "been retried."
    ),
    "support-thread-8831": (
        "Customer writes: every few days our queue depth climbs for about an "
        "hour and nothing in the dashboard explains it. We eventually find one "
        "endpoint timing out and everything else stuck behind it."
    ),
    "migration-steps": (
        "Before upgrading, rename worker.retry_attempts to queue.max_attempts "
        "in your config. A deploy that keeps the old key starts with the "
        "default of three attempts and logs a warning once. Inspecting dead "
        "letters needs the new queues:read scope on the API token."
    ),
    "benchmark-note-1004": (
        "Replaying one tenant's October 4 traffic against 4.2, p99 job latency "
        "fell and the worker pool never saturated. Measured on one tenant's "
        "replay on staging hardware. Not a general performance claim and not "
        "to be written as one."
    ),
    "roadmap-draft-q4": (
        "NOT FOR PUBLICATION. Draft plans for per-tenant queue priorities and "
        "a managed dead-letter replay screen. Neither is committed and neither "
        "has a date."
    ),
}

EMBARGOED = frozenset({"roadmap-draft-q4"})
PUBLISHABLE = [sid for sid in SOURCES if sid not in EMBARGOED]

BRIEF = (
    "Write the release post for Scheduler 4.2, for operators who run the "
    "service themselves. They need to know what changed, what it means for "
    "the way their jobs behave, and what they must do before upgrading."
)

_BULLET = re.compile(r"^\s*(?:[-*•]|\d+[.)])\s*")
_CITATION = re.compile(r"\[([a-z0-9\-:]+)\]")

PLAN_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You plan a release post as a list of sections. One section per "
            "line, in this exact form:\n"
            "heading :: source-id,source-id :: what this section must establish"
            "\nNo numbering, no commentary, no blank lines. Use only source ids "
            "from the index you are given. A section names every source it "
            "needs and none it does not. Give the breaking change and the steps "
            "before upgrading their own section rather than a paragraph inside "
            "another one. At most {max_sections} sections.",
        ),
        ("human", "Brief:\n{brief}\n\nSource index:\n{index}"),
    ]
)

WRITE_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You write one section of a release post for operators who run the "
            "service themselves. Around {words} words. Every sentence that "
            "states a fact ends with the id of the source it came from, in "
            "square brackets. Write from the sources below and from nothing "
            "else: if they do not support a claim, leave it out. Never state a "
            "measurement more broadly than the conditions its source gives. No "
            "heading, no preamble, no sign-off — the body of the section only. "
            "Apply the revision note exactly and change nothing else.",
        ),
        (
            "human",
            "Section heading: {heading}\nThis section must establish: {angle}\n\n"
            "Sources:\n{sources}\n\nRevision note:\n{note}",
        ),
    ]
)

EDIT_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You edit a post whose sections were written separately and could "
            "not see each other. Report only faults that cross sections or "
            "misstate a source: the same fact explained twice, two sections "
            "that disagree, a measurement stated more broadly than its source "
            "allows, a change that needs a migration step the post never "
            "gives. Reply with the single word CLEAN, or one line per section "
            "to fix, in this exact form:\n"
            "heading :: what to change\n"
            "At most {max_fixes} lines, worst first. Never rewrite the text "
            "yourself.",
        ),
        ("human", "Brief:\n{brief}\n\nDraft:\n{draft}"),
    ]
)

TITLE_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You write the title and the one-sentence standfirst for the post "
            "you are given. Exactly two lines: the title first, the standfirst "
            "second. The title is a plain statement of what changed, under "
            "sixty characters, no colon and no wordplay. The standfirst says "
            "who has to do something before upgrading and what it is. Add "
            "nothing else.",
        ),
        ("human", "{draft}"),
    ]
)

planner_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)
writer_llm = ChatAnthropic(model=WRITE_MODEL, max_tokens=700, temperature=0)
editor_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)
summarizer_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=192, temperature=0)

plan_chain = PLAN_PROMPT | planner_llm | StrOutputParser()
write_chain = WRITE_PROMPT | writer_llm | StrOutputParser()
edit_chain = EDIT_PROMPT | editor_llm | StrOutputParser()
title_chain = TITLE_PROMPT | summarizer_llm | StrOutputParser()


@dataclass
class Section:
    heading: str
    sources: list[str]
    angle: str


def source_index() -> str:
    return "\n".join(
        f"{sid}: {' '.join(SOURCES[sid].split()[:12])}..." for sid in PUBLISHABLE
    )


def source_notes(source_ids: list[str]) -> str:
    return "\n\n".join(f"[{sid}]\n{SOURCES[sid]}" for sid in source_ids)


def _lines(text: str, limit: int) -> list[str]:
    cleaned = (_BULLET.sub("", line).strip() for line in text.splitlines())
    return [line for line in cleaned if line][:limit]


def assemble(sections: list[Section], drafts: list[str]) -> str:
    return "\n\n".join(
        f"## {section.heading}\n\n{body.strip()}"
        for section, body in zip(sections, drafts, strict=True)
        if body.strip()
    )


def off_source(body: str, allowed: list[str]) -> list[str]:
    return sorted(set(_CITATION.findall(body)) - set(allowed))


def leaked(body: str) -> list[str]:
    return sorted(set(_CITATION.findall(body)) & EMBARGOED)


def plan(brief: str) -> list[Section]:
    raw = plan_chain.invoke(
        {"brief": brief, "index": source_index(), "max_sections": MAX_SECTIONS}
    )
    sections: list[Section] = []
    seen: set[str] = set()
    for line in _lines(raw, MAX_SECTIONS):
        parts = [part.strip() for part in line.split("::")]
        if len(parts) != 3 or not parts[0] or parts[0] in seen:
            continue
        allowed = [sid for sid in parts[1].split(",") if sid.strip() in PUBLISHABLE]
        if not allowed:
            continue
        seen.add(parts[0])
        sections.append(
            Section(
                heading=parts[0],
                sources=[sid.strip() for sid in allowed],
                angle=parts[2],
            )
        )
    return sections


def write_sections(sections: list[Section], notes: dict[str, str]) -> list[str]:
    return write_chain.batch(
        [
            {
                "heading": section.heading,
                "angle": section.angle,
                "sources": source_notes(section.sources),
                "note": notes.get(section.heading, "none"),
                "words": SECTION_WORDS,
            }
            for section in sections
        ],
        config={"max_concurrency": WRITE_CONCURRENCY},
    )


def review(brief: str, sections: list[Section], drafts: list[str]) -> dict[str, str]:
    raw = edit_chain.invoke(
        {
            "brief": brief,
            "draft": assemble(sections, drafts),
            "max_fixes": MAX_FIXES,
        }
    )
    if raw.strip().upper().startswith("CLEAN"):
        return {}
    headings = {section.heading for section in sections}
    fixes: dict[str, str] = {}
    for line in _lines(raw, MAX_FIXES):
        heading, _, note = line.partition("::")
        if heading.strip() in headings and note.strip():
            fixes[heading.strip()] = note.strip()
    return fixes


def headline(post: str) -> tuple[str, str]:
    lines = _lines(title_chain.invoke({"draft": post}), 2)
    if not lines:
        return ("", "")
    return (lines[0], lines[1] if len(lines) > 1 else "")


def write_post(brief: str) -> dict[str, Any]:
    sections = plan(brief)
    if not sections:
        return {"post": None, "reason": "the planner produced no usable sections"}

    drafts = write_sections(sections, {})
    fixes = review(brief, sections, drafts)
    rounds = 0
    while fixes and rounds < MAX_ROUNDS:
        targets = [s for s in sections if s.heading in fixes]
        rewritten = write_sections(targets, fixes)
        by_heading = dict(zip([s.heading for s in targets], rewritten, strict=True))
        drafts = [
            by_heading.get(s.heading, body)
            for s, body in zip(sections, drafts, strict=True)
        ]
        rounds += 1
        fixes = review(brief, sections, drafts)

    post = assemble(sections, drafts)
    title, standfirst = headline(post)
    return {
        "post": post,
        "title": title,
        "standfirst": standfirst,
        "reason": None,
        "sections": [s.heading for s in sections],
        "rounds": rounds,
        "unresolved": sorted(fixes),
        "off_source": sorted(
            {
                sid
                for s, body in zip(sections, drafts, strict=True)
                for sid in off_source(body, s.sources)
            }
        ),
        "leaked": sorted({sid for body in drafts for sid in leaked(body)}),
    }


if __name__ == "__main__":
    result = write_post(BRIEF)
    if result["post"] is None:
        print(f"no post: {result['reason']}")
    else:
        print(result["title"])
        print(result["standfirst"])
        print()
        print(result["post"])
        print(
            f"\n{len(result['sections'])} section(s), "
            f"{result['rounds']} edit round(s)"
        )
        if result["unresolved"]:
            print(f"editor still flags: {', '.join(result['unresolved'])}")
        if result["off_source"]:
            print(f"cited outside its sources: {', '.join(result['off_source'])}")
        if result["leaked"]:
            print(f"EMBARGOED SOURCE CITED: {', '.join(result['leaked'])}")
python draft.py
You get a titled post with a source id on every factual sentence, the number of sections the planner chose, how many edit rounds ran, and anything the checks caught. The interesting output is the section list: a planner that gave the config rename its own section produced a post an operator can act on, and one that folded the rename into What changed produced a post that buries the only sentence that will break a deploy. Both are real outcomes of an agent shaped like this, and the difference costs one call on the cheap model.
The application is finished. Nothing below changes what it does.
Seeing what it cost
What you do not have is any idea which of the four roles spent the money. The provider's invoice has one line for the API key, and the four to thirteen calls behind it are indistinguishable — same key, same account, three of the four roles on the same model.
pip install capsera
At the top of draft.py, above everything else:
# fragment
import os

import capsera

capsera.init(api_key=os.environ["CAPSERA_API_KEY"], endpoint="https://api.capsera.ai")
That is the capture step, and it is already complete. capsera.init() patches
the provider client that ChatAnthropic constructs underneath, so from that call
on every request the agent makes is recorded: the planner's, each writer's inside
batch(), the editor's, the summarizer's. The prompts are untouched, the chains
are untouched, batch() is untouched, and no traffic changed route — the SDK runs
inside your process rather than in front of it, so there is no proxy, no
base_url to swap and nothing new in the request path.
One addition for a script: a background thread ships events on an interval, so a process that exits immediately can exit before the queue drains.
# fragment
if __name__ == "__main__":
    result = write_post(BRIEF)
    print(result["post"])
    capsera.shutdown()
capsera.shutdown() flushes pending events and stops the worker. A long-running
service does not need it; a script, a cron job or a notebook cell does, and
omitting it is the usual reason a first run reports nothing.
Run it now and you have a total, a per-model split and token counts per call. You
also have every one of those events attributed to unknown, because nothing has
said which role made it. unknown is a real row, not a dropped one — an
unattributed cost is still a cost — but it is one row where you wanted four.
Name the roles
The calls are already captured. The decorator only says who:
# fragment
@capsera.agent("planner", team="release-desk", task_type="outline")
def plan(brief: str) -> list[Section]:
    ...  # body unchanged


@capsera.agent("writer", team="release-desk", task_type="section-draft")
def write_sections(sections: list[Section], notes: dict[str, str]) -> list[str]:
    ...  # body unchanged


@capsera.agent("editor", team="release-desk", task_type="cross-section-review")
def review(brief: str, sections: list[Section], drafts: list[str]) -> dict[str, str]:
    ...  # body unchanged


@capsera.agent("summarizer", team="release-desk", task_type="title")
def headline(post: str) -> tuple[str, str]:
    ...  # body unchanged
Four added lines, and that is the entire diff. No function body changed, no call site changed, no model construction changed, no argument threaded through the supervisor. Every LLM call made while a decorated function is on the stack is attributed to that agent, including calls made by the functions it calls and by the framework it invokes.
The fan-out keeps its identity. write_sections does its work in
write_chain.batch(...), which dispatches to worker threads rather than calling
on the thread you were on, and the writer scope is still what gets recorded.
Capsera holds the attribution stack in a ContextVar and LangChain's batch()
dispatches through a context-copying executor, so the scope the caller was in is
the scope the worker sees — verified empirically on LangChain 1.3 with capsera
0.3.0. batch() also produces one event per underlying call rather than one per
batch, so six sections are six writer events
(coverage table).
The credit there belongs to LangChain, and it is worth knowing where the
guarantee stops. A ContextVar does not cross a thread boundary on its
own — it crosses when the code starting the thread copies the context, which
batch() does and a hand-rolled pool does not. Draft the sections yourself with
a bare ThreadPoolExecutor and the same decorator records unknown instead of
writer, with no error to tell you. Measured on the same versions:
# fragment
import contextvars
from concurrent.futures import ThreadPoolExecutor

# Loses the scope: workers start with a fresh context.
with ThreadPoolExecutor(max_workers=WRITE_CONCURRENCY) as pool:
    drafts = list(pool.map(write_one, planned))

# Keeps it: hand each worker a copy of the caller's context.
ctx = contextvars.copy_context()
with ThreadPoolExecutor(max_workers=WRITE_CONCURRENCY) as pool:
    drafts = list(pool.map(lambda s: ctx.run(write_one, s), planned))
Async needs nothing extra — a ContextVar is snapshotted per task, so roles
awaited concurrently under asyncio.gather keep their own attribution.
Leave the supervisor undecorated. write_post makes no LLM call of its own;
every call inside it happens while one of the four roles is on the stack, and the
innermost scope is the one recorded. Decorating it would add a row that can never
have spend on it. For a per-brief total, use the team field — which is what
team="release-desk" on all four decorators is for.
Cost the rewrites separately
The rewrite pass is the part of this agent whose cost you cannot see from the role
rows alone. A post that passed review first time and a post that sent three
sections back both report as writer, on the expensive model, and the row says
nothing about which. capsera.tag() opens a sub-scope inside a function you have
already decorated, which is exactly this case:
# fragment
import capsera


@capsera.agent("writer", team="release-desk", task_type="section-draft")
def write_sections(sections: list[Section], notes: dict[str, str]) -> list[str]:
    if not notes:
        return _write(sections, notes)
    # A rewrite is the same agent writing the same section again against an
    # editor's note. Cost the second pass separately from the first.
    with capsera.tag("writer", team="release-desk", task_type="section-rewrite"):
        return _write(sections, notes)
_write is the original body, moved down one level and otherwise unchanged. The
rewrite keeps the agent name, so a budget scoped to writer still counts both
passes, and it changes the task type, so the share of writing spend that came from
failed reviews is a number you can read instead of a suspicion.
Use tag() for a genuine sub-scope like this one. It is the wrong tool for naming
an iteration: tagging each section with its heading would give you one row per
heading, most of which never appear on the next brief, and an agent budget cannot
accumulate against a name that lived for one post. The per-invocation axis has its
own fields on the same event — customer_id and cost_center on
@capsera.agent, session_id on capsera.tag — so you can slice by which
product or which team a post was for without fragmenting the agent dimension that
budgets and cost attribution depend on.
Put a budget on the role that multiplies
The planner makes one call per brief. The editor makes one plus one more if anything was rewritten, and the summarizer makes one. All of those counts are in your file. The writer's is not: it is the number of sections a model chose to plan, plus the number of them another model chose to send back. Point this agent at a release with twenty notes instead of six and the other three rows barely move — the planner's prompt grows by a few index lines, the editor reads a longer draft once — while the writer's row grows with the section count and with the length of the sources each section carries.
That is the part worth saying plainly, because it is the opposite of the usual case. In a RAG pipeline the multiplied role is the cheapest one, a one-word relevance vote you can afford to run fifty times. Here the multiplied role is the one on the stronger model with the longest prompts, so both halves of the multiplication grow at once. That is multi-agent amplification in one sentence, and it is why the cap belongs on the writer rather than on the run.
Create the budget in the dashboard with scope agent and the agent set to
writer — the same string as the decorator. That string is the whole join between
the two halves of this page: a budget can only act on a boundary the events carry,
and spend attributed to unknown cannot be governed by a
per-agent budget. Pick the amount from a week of
your own drafting spend rather than a figure from a tutorial, and set the action
to block.
Enforcement is on by default (enable_budget_enforcement=True in init()) and
the check runs before the provider call. When the writer is over its budget,
BudgetExceededError is raised inside your process and the request never leaves
it, so no tokens are spent on it. This is
pre-call enforcement: the check happens where
your code is, not in front of the provider, and a blocked call costs you the check
rather than the completion.
Then decide what a blocked section means for the post. batch() raises on the
first failure and abandons the remaining inputs unless you tell it otherwise, so
this is a decision you make rather than one you inherit:
# fragment
import capsera


def _write(sections: list[Section], notes: dict[str, str]) -> tuple[list[str], list[str]]:
    """Returns one body per section, and the headings a budget stopped."""
    results = write_chain.batch(
        [
            {
                "heading": section.heading,
                "angle": section.angle,
                "sources": source_notes(section.sources),
                "note": notes.get(section.heading, "none"),
                "words": SECTION_WORDS,
            }
            for section in sections
        ],
        config={"max_concurrency": WRITE_CONCURRENCY},
        return_exceptions=True,
    )

    drafts: list[str] = []
    missing: list[str] = []
    for section, body in zip(sections, results, strict=True):
        if isinstance(body, capsera.BudgetExceededError):
            drafts.append("")
            missing.append(section.heading)
            continue
        if isinstance(body, BaseException):
            raise RuntimeError(f"writing {section.heading} failed: {body}")
        drafts.append(body)
    return drafts, missing
return_exceptions=True asks batch() to hand failures back as items in the
result list instead of raising on the first one, which is what lets you tell a
budget block from a flaky call and name the sections that went unwritten. Without
it, one blocked section ends the drafting pass and the rest are never even
attempted.
_write now returns two values, so the decorated write_sections wrapper above
returns them too — its annotation becomes tuple[list[str], list[str]] and its
body is otherwise the same two lines. The decorator and the tag() scope do not
change.
An empty body is the one case assemble already handles, so a stopped section
leaves no empty heading in the document. That is also the trap: a post with a
section missing reads as finished. A truncated answer looks truncated; a
four-section post that should have had six looks like a four-section post, and
the sentence an operator needed about renaming a config key is simply not there.
So the headings travel with the result, and the roles downstream are told:
# fragment
from typing import Any


def write_post(brief: str) -> dict[str, Any]:
    sections = plan(brief)
    if not sections:
        return {"post": None, "reason": "the planner produced no usable sections"}

    drafts, missing = write_sections(sections, {})
    if not any(drafts):
        return {"post": None, "reason": "the writer budget stopped every section"}

    # The editor is reviewing a post with holes in it. Say so, or it reports
    # the holes as faults in the sections that did get written.
    fixes = {} if missing else review(brief, sections, drafts)
    post = assemble(sections, drafts)
    return {
        "post": post,
        "reason": None,
        # Not a complete draft. Do not publish this without reading `missing`.
        "partial": bool(missing),
        "missing": missing,
        "sections": [s.heading for s in sections if s.heading not in missing],
        "unresolved": sorted(fixes),
    }
Skipping the review when sections are missing is a cost decision and a quality one at the same time. An editor handed a post with a hole will spend its three fixes describing the hole, and each of those fixes is a rewrite call on the model whose budget just ran out. The run that cannot afford to write cannot afford to review either.
The single-call roles still need somewhere for a refusal to land. plan, review
and headline call invoke() directly, so there is no return_exceptions to
catch a block for them — if you also put a budget on planner or on the
release-desk team, it surfaces as a raise:
# fragment
from typing import Any

import capsera


def run_once(brief: str) -> dict[str, Any] | None:
    """Returns None when a budget stopped a role that makes a single call."""
    try:
        return write_post(brief)
    except capsera.BudgetExceededError as exc:
        print(f"budget reached before a draft existed: {exc}")
        return None
BudgetExceededError is the only exception the SDK raises deliberately;
everything else fails open. Do not catch it and retry immediately — the budget
will still be exceeded. Lowering MAX_SECTIONS and rerunning, queueing the brief
until the period rolls over, and failing are all defensible; for an agent drafting
from a queue, queueing usually is, because a release post is rarely needed in the
next sixty seconds.
Three limits to know before you rely on this as a hard ceiling.
The blast radius is the role, not the run. A budget on writer stops writing
calls. The planner, the editor and the summarizer are different agents with no
budget on them, so a brief still gets planned and a partial post still gets
titled — and a title over a post with two sections missing is the most confident
artefact in this whole pipeline. That is worth deciding on purpose: if what you
want capped is the whole desk, that is a team-scoped budget, not a side effect of
this one.
A parallel drafting pass can overshoot. The check reads budget state computed
from delivered events, and events are delivered in batches on an interval
(flush_interval_ms, 500 ms by default), so a burst of concurrent calls can each
pass a check taken before any of them was recorded. Here the burst is
WRITE_CONCURRENCY — three as shipped, and whatever you raise it to when posts
get longer. Set the budget below a figure you cannot exceed, or lower the
concurrency; it is the concurrency that decides the overshoot, not MAX_SECTIONS.
It fails open, on purpose. If the pre-call check does not complete within
budget_check_timeout (1 second by default), the call is allowed. A network
problem between your service and Capsera should not halt production traffic. Of
the three actions, block and margin downgrade act at runtime; throttle records
the decision but does not delay the call. The full behaviour is in
budgets and enforcement.
What this run actually cost
No dollar figures on this page: this agent has not been run against a real key, and a number invented here would not be yours anyway — it depends on your notes, how many sections your planner writes, and today's prices. What is worth predicting is the shape of the result.
Four agent rows — planner, writer, editor, summarizer — under one team,
release-desk, with a cost per run for the brief as a
whole, and the writer row split by task type into section-draft and
section-rewrite.
Read each row as call count and cost per call, not as a total. Three things move
on this agent and each has a different fix. The writer's call count moving means
the planner is cutting the post into more sections, which is a planning change
rather than a writing one and costs the stronger model every time. The
section-rewrite share moving means the editor is sending more back, which is the
expensive kind of movement because each rewrite pays the stronger model again and
buys a second editor call. And the writer's cost per call moving means the
sections are being assigned more sources, which is the one you can fix in the
planner prompt.
Expect the writer row to dominate, and check rather than assume — on a brief with one long source assigned to every section, the editor's single call over the whole draft can be larger than it looks, because its input is the assembled post and grows with everything the writer produced.
The planner and the editor are the rows with the most repetition in them, and
repetition is the one place a cheap call can get cheaper. Every writer call in a
pass carries the same instruction and differs only in the heading and the sources,
so a long, identical prefix sits in front of six requests. The cache read share
column is what tells you whether any of it was billed six times instead of once;
it is a number to read rather than one to predict, because a shared prefix has to
be long enough and identical enough to be worth anything, and putting the
instruction before the sources is what earns it. Turning on
enable_prompt_analysis=True in init() puts a figure on how often one
system-prompt hash repeats, which is the evidence for whether that restructuring
is worth doing: prompt caching that never
engaged.
Each event also carries the file that made the call, which points at draft.py
rather than into langchain_core, so a row you did not expect traces back to code
rather than to a model name.
Questions this page answers
How do I get per-agent cost for a LangChain content agent? Call
capsera.init() once, which patches the provider client ChatAnthropic
constructs underneath, so every call the agent makes is already recorded. Then put
@capsera.agent("<role>") on each role function — the planner, the section
writer, the editor, the summarizer. The decorator says who made the call; it does
not change whether the call is captured, and no function body, call site or model
construction changes.
Which agent in a content pipeline should carry the budget? The section writer, because it is the only role whose call count is not a constant in your file. The planner decides how many sections the post has, and the writer runs once per section plus once per section the editor sends back. The planner, the editor and the summarizer are one call each per round.
Why does the section writer cost more than the rest of a content agent combined? Because it is the only role that is both multiplied and expensive. The planner, the editor and the summarizer read short inputs on the cheap model and run once; the writer runs once per section on the model whose prose a reader will actually see, with the full text of every source that section was assigned in the prompt. Both halves of its row grow at once — more sections and longer sources — which is the opposite of a RAG grader, where the multiplied role is the cheapest one.
What should a content agent do when a budget stops part of the draft? Assemble the post from the sections that were written and carry the headings that were not out with it. A document with a hole in it looks finished in a way a truncated answer does not, so the missing headings have to reach whatever renders the draft. Never let the editor or the summarizer run over a partial post without knowing it is partial: an editor asked to review a draft with a section missing will report the gap as a flaw in the sections that are there.
Questions this page answers
- How do I get per-agent cost for a LangChain content agent?
- Call capsera.init() once, which patches the provider client ChatAnthropic constructs underneath, so every call the agent makes is already recorded. Then put @capsera.agent("<role>") on each role function — the planner, the section writer, the editor, the summarizer. The decorator says who made the call; it does not change whether the call is captured, and no function body, call site or model construction changes.
- Which agent in a content pipeline should carry the budget?
- The section writer, because it is the only role whose call count is not a constant in your file. The planner decides how many sections the post has, and the writer runs once per section plus once per section the editor sends back. The planner, the editor and the summarizer are one call each per round.
- Why does the section writer cost more than the rest of a content agent combined?
- Because it is the only role that is both multiplied and expensive. The planner, the editor and the summarizer read short inputs on the cheap model and run once; the writer runs once per section on the model whose prose a reader will actually see, with the full text of every source that section was assigned in the prompt. Both halves of its row grow at once — more sections and longer sources — which is the opposite of a RAG grader, where the multiplied role is the cheapest one.
- What should a content agent do when a budget stops part of the draft?
- Assemble the post from the sections that were written and carry the headings that were not out with it. A document with a hole in it looks finished in a way a truncated answer does not, so the missing headings have to reach whatever renders the draft. Never let the editor or the summarizer run over a partial post without knowing it is partial: an editor asked to review a draft with a section missing will report the gap as a flaw in the sections that are there.
Give every agent an identity, a budget, and hard limits.
One line of code. Anthropic, OpenAI, and Google Gemini.
See pricing