
Per-attempt cost in a LangGraph code repair loop
A planner, parallel patchers and a test runner in LangGraph 1.x on Claude, then per-agent cost and a blocking budget on the role that fans out.
- Framework
- LangGraph 1.x
- Provider
- anthropic
- Python
- 3.11+
- Capsera
- pip install capsera
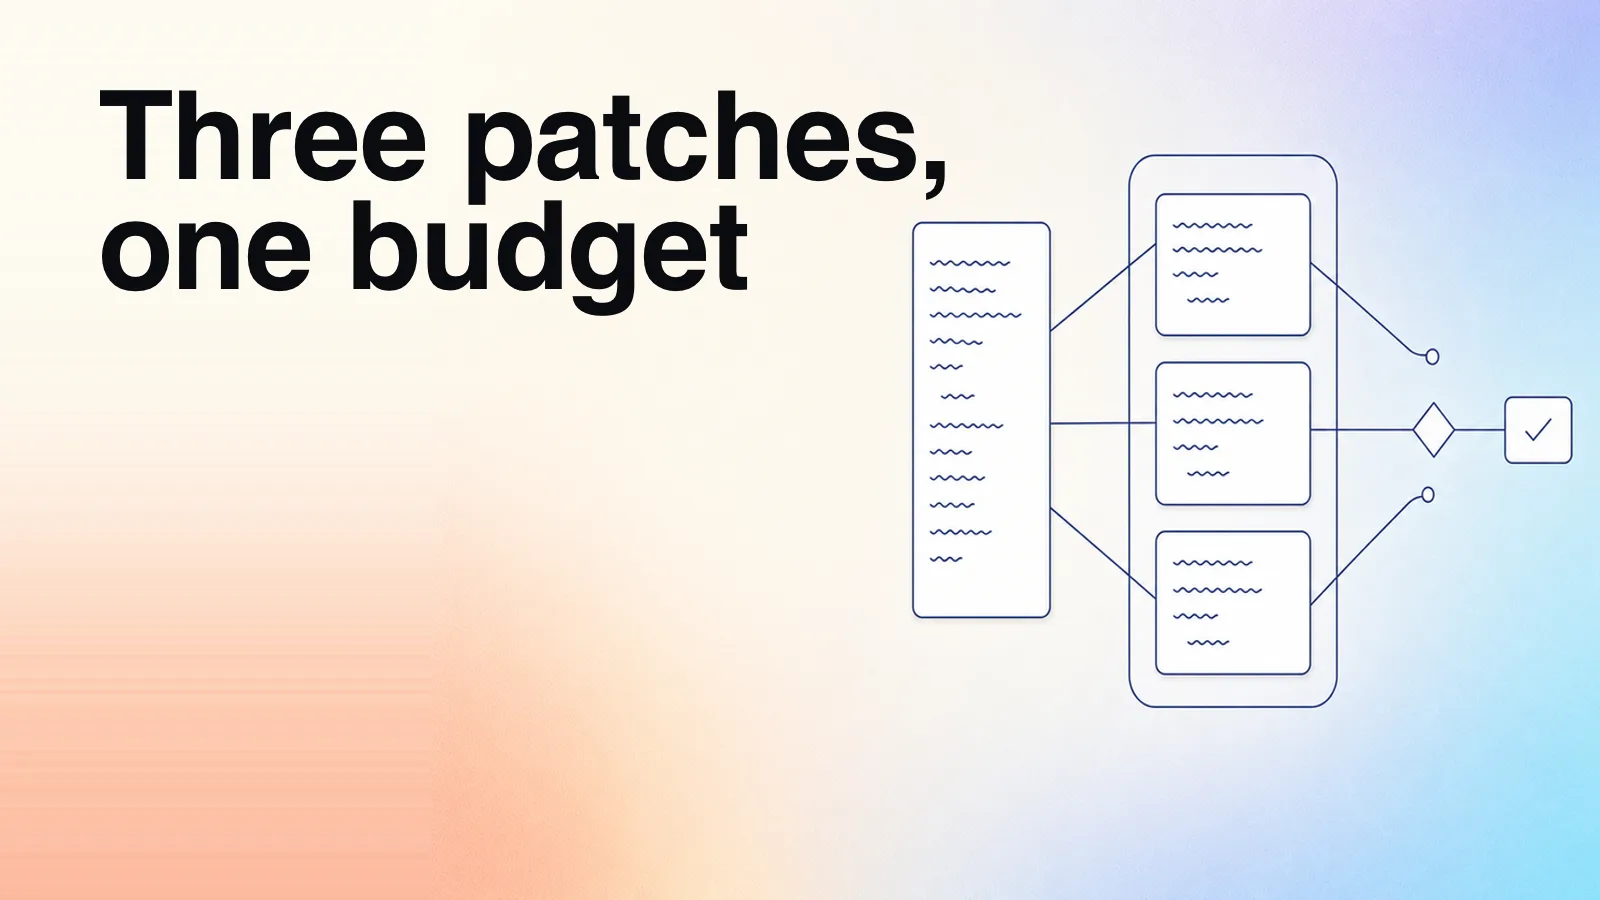
This builds a code repair loop in LangGraph 1.x against Anthropic: a planner
reads a failing check report and names up to three files that might hold the
defect, patchers rewrite those files in parallel, a test runner executes each
candidate in a subprocess, and a reviewer picks a patch that passes without
gaming the checks. One repair is between 1 and 9 model calls, and where in that
range a run lands is decided by a model rather than by your code. The last third
of this page adds Capsera: one init() call to capture every request, three
decorator lines to say which role made it, and a blocking budget on the role
that fans out.
What you will build
repair.py, a single-file LangGraph app with three model roles, one free one,
and a loop:
- planner — one call per attempt. Reads the failing checks and an index of
the files it may change, and writes at most
MAX_HYPOTHESESlines, each a file path and one sentence naming the defect in it. - patcher — one call per hypothesis, run in parallel, on the stronger model. Rewrites one file in full, or declines. The multiplier.
- verifier — no model call. Writes each candidate to a temporary directory and runs the checks in a subprocess. Decides whether the loop ends.
- reviewer — one call, only if something passed. Rejects a patch that special-cases the values the checks use, and names the one to apply.
The graph is a cycle. The planner's successor is a conditional edge that returns
one Send per hypothesis, the branches merge through a reducer, and the
verifier's edge points either at the reviewer, back at the planner, or at the
end. What breaks the cycle is a subprocess exit code, not a model.
The agent proposes; it never writes to your working tree. The patcher returns
file contents, the diff is computed in Python with difflib, and what you read
at the end is a unified diff of a change that was never applied.
Each role is its own function, and the function that only routes is not one of them. That matters later — it is the seam the instrumentation attaches to — and it is the better shape regardless, because a supervisor that inlines three model calls has nothing you can name, budget, or move to a different model.
Written against LangGraph 1.x with langchain-anthropic, calling Anthropic's
API directly rather than through a gateway. Models: claude-haiku-4-5 for the
planner and the reviewer, claude-sonnet-5 for the patcher.
Prerequisites
Python 3.11 or newer.
pip install "langgraph>=1.0,<2" langchain-anthropic
The major is pinned so this page stays true as LangGraph moves.
langchain-anthropic is left unpinned on purpose: install the one that matches
your langgraph major.
You need an Anthropic API key. ChatAnthropic reads ANTHROPIC_API_KEY from
the environment, so export it and no code has to touch it:
export ANTHROPIC_API_KEY=...
Step 1 — Fix the repository, and make the failure a fact
Start with the repository and the checks, not the agent. A coding agent pointed at a real checkout has an unbounded number of calls in it, because every tool call it makes to look around is a call you pay for. An agent handed a fixed snapshot and a fixed set of checks has a call count you can multiply out before you run anything, and — more usefully — it has one thing in the loop that answers "did that work?" without asking a model.
The snapshot below is a shipping quote with a real off-by-one in it. Band rates
are looked up with < where the band table means "up to and including", so a
parcel that weighs exactly a band limit is priced into the next band up. Two
checks fail because of it. A third file, rounding.py, is correct and looks
implicated, because half-up money rounding is the kind of thing that attracts a
patch.
"""repair.py — the repository snapshot and the checks that bound the loop."""
import pathlib
import subprocess
import sys
import tempfile

TEST_TIMEOUT = 10      # seconds a candidate gets before it is failed
FAILURE_CHARS = 800    # of check output carried into a prompt

SNAPSHOT = {
    "rates.py": (
        "BANDS = (\n"
        "    (1.0, 4.50),\n"
        "    (5.0, 7.25),\n"
        "    (20.0, 13.00),\n"
        ")\n"
        "\n"
        "OVERWEIGHT_RATE = 0.85  # per kg above the last band\n"
    ),
    "rounding.py": (
        "from decimal import ROUND_HALF_UP, Decimal\n"
        "\n"
        "\n"
        "def to_cents(amount):\n"
        "    quantized = Decimal(str(amount)).quantize(\n"
        "        Decimal('0.01'), rounding=ROUND_HALF_UP\n"
        "    )\n"
        "    return float(quantized)\n"
    ),
    "quote.py": (
        "from rates import BANDS, OVERWEIGHT_RATE\n"
        "from rounding import to_cents\n"
        "\n"
        "\n"
        "def billable_weight(actual_kg, length_cm, width_cm, height_cm):\n"
        "    volumetric = (length_cm * width_cm * height_cm) / 5000.0\n"
        "    return max(actual_kg, volumetric)\n"
        "\n"
        "\n"
        "def band_rate(weight_kg):\n"
        "    for limit, rate in BANDS:\n"
        "        if weight_kg < limit:\n"
        "            return rate\n"
        "    top_limit, top_rate = BANDS[-1]\n"
        "    return top_rate + (weight_kg - top_limit) * OVERWEIGHT_RATE\n"
        "\n"
        "\n"
        "def quote(actual_kg, dims_cm, surcharge=0.0):\n"
        "    weight = billable_weight(actual_kg, *dims_cm)\n"
        "    return to_cents(band_rate(weight) + surcharge)\n"
    ),
}

TESTS = (
    "from quote import band_rate, billable_weight, quote\n"
    "\n"
    "FAILURES = []\n"
    "\n"
    "\n"
    "def check(name, got, want):\n"
    "    if abs(got - want) > 1e-9:\n"
    "        FAILURES.append(f'{name}: expected {want}, got {got}')\n"
    "\n"
    "\n"
    "check('below the first band', band_rate(0.4), 4.50)\n"
    "check('on the first boundary', band_rate(1.0), 4.50)\n"
    "check('into the second band', band_rate(1.1), 7.25)\n"
    "check('on the last boundary', band_rate(20.0), 13.00)\n"
    "check('above the last band', band_rate(22.0), 14.70)\n"
    "check('volumetric weight wins', billable_weight(0.5, 30, 20, 10), 1.2)\n"
    "check('quote rounds half up', quote(1.0, (10, 10, 10), 0.005), 4.51)\n"
    "\n"
    "if FAILURES:\n"
    "    print('FAILED ' + str(len(FAILURES)) + ' of 7 checks')\n"
    "    for line in FAILURES:\n"
    "        print(line)\n"
    "    raise SystemExit(1)\n"
    "\n"
    "print('all checks passed')\n"
)


def run_tests(files: dict[str, str]) -> tuple[bool, str]:
    """Run the checks against a candidate snapshot. No model involved."""
    with tempfile.TemporaryDirectory() as tmp:
        root = pathlib.Path(tmp)
        for path, text in {**files, "run_checks.py": TESTS}.items():
            target = root / path
            target.parent.mkdir(parents=True, exist_ok=True)
            target.write_text(text)
        try:
            proc = subprocess.run(
                [sys.executable, "run_checks.py"],
                cwd=root,
                capture_output=True,
                text=True,
                timeout=TEST_TIMEOUT,
            )
        except subprocess.TimeoutExpired:
            return False, f"the checks did not finish within {TEST_TIMEOUT}s"
    output = (proc.stderr.strip() or proc.stdout.strip())[-FAILURE_CHARS:]
    return proc.returncode == 0, output


def file_index() -> str:
    return "\n".join(
        f"{path} ({len(text.splitlines())} lines)" for path, text in SNAPSHOT.items()
    )


if __name__ == "__main__":
    passed, output = run_tests(SNAPSHOT)
    print("passed" if passed else "failing")
    print(output)
Run that on its own and you get the report the whole loop is built around: two of seven checks failing, each naming the value it expected and the value it got. Nothing in this block imports a model library, and that is worth noticing before the rest of the page arrives — the hard part of a repair agent is the oracle, and the oracle here costs an exit code.
The checks live outside SNAPSHOT, so they are not a file the agent can
rewrite. That single decision removes the most common way a repair loop
"succeeds": editing the assertion instead of the code. It does not remove the
other way, which is a patch that special-cases the exact inputs the checks use,
and that is the reviewer's job later.
FAILURE_CHARS is a cost decision, not tidiness. Check output goes into a
planner prompt and a patcher prompt, and a traceback from a badly generated
patch can be thousands of tokens of someone else's stack frames. Truncating from
the end keeps the assertion and drops the preamble.
Step 2 — The state, and where the loop is bounded
Two things here are not obvious. candidates needs a reducer because branches
write to it concurrently — operator.add concatenates the lists instead of the
last branch overwriting the rest. And attempts exists because a repair loop
has no natural end: a planner given a failing report will always find one more
file worth suspecting, and every lap is a planner call plus up to
MAX_HYPOTHESES patcher calls on the expensive model.
# fragment
import operator
from typing import Annotated, TypedDict

MAX_ATTEMPTS = 2        # planning rounds. A real loop raises this to ~4.
MAX_HYPOTHESES = 3      # candidate patches per round.
ROUND_CONCURRENCY = 3   # patchers in flight at once
CLAIM_CHARS = 160       # of a planner hypothesis kept
HISTORY_CHARS = 200     # of a candidate's failure kept for the next planner


class Task(TypedDict):
    """The payload one branch receives. Not the graph's state."""

    attempt: int
    path: str
    claim: str
    failure: str


class Candidate(TypedDict):
    key: str
    path: str
    claim: str
    source: str  # "" when the patcher declined
    note: str


class Result(TypedDict):
    key: str
    passed: bool
    output: str


class RepairState(TypedDict):
    attempts: int
    tasks: list[Task]
    candidates: Annotated[list[Candidate], operator.add]
    results: Annotated[list[Result], operator.add]
    failure: str
    verdict: str


def history_text(candidates: list[Candidate], results: list[Result]) -> str:
    by_key = {result["key"]: result for result in results}
    lines = []
    for candidate in candidates:
        result = by_key.get(candidate["key"])
        if result is None:
            outcome = candidate["note"] or "no patch produced"
        elif result["passed"]:
            outcome = "passed the checks"
        else:
            tail = result["output"][-HISTORY_CHARS:].replace("\n", " ")
            outcome = f"still failing: {tail}"
        lines.append(f"{candidate['path']}: {candidate['claim']} -> {outcome}")
    return "\n".join(lines) or "none"
Task carries failure even though it is already in the state. A branch
started by Send receives the payload as its whole input, not the graph state,
so anything the patcher needs has to be in the payload. Writing that out is
better than reaching for a module-level global, because it makes the branch's
dependencies a type you can read.
key is attempt:path, and it is what lets the verifier tell a candidate it has
already run from one it has not. Without it, round two re-runs round one's
patches — free in subprocess time, but it also re-reports them to the reviewer.
Multiply the first two constants and you have the cost model of this program: at
most MAX_ATTEMPTS planner calls, MAX_ATTEMPTS × MAX_HYPOTHESES patcher calls
and one reviewer call. Nine, as shipped. One, if the planner looks at the report
and names no file it is allowed to change.
Step 3 — The planner, and the delegation it is allowed to make
The planner is the only role that decides what runs next, and everything it decides costs money on the expensive model. So the constraints live in Python rather than in the prompt. A model asked for "at most three" will occasionally write five, and a model asked to name a different file each time will occasionally name the same one twice — which is two branches, two calls and two rewrites of one file.
# fragment
from langchain_anthropic import ChatAnthropic
from langchain_core.output_parsers import StrOutputParser
from langchain_core.prompts import ChatPromptTemplate
from langgraph.graph import END
from langgraph.types import Send

FAST_MODEL = "claude-haiku-4-5"

PLANNER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You localize a defect from a failing check report. Write at most "
            "{max_hypotheses} lines. Each line is a file path, two colons, and "
            "one sentence naming the specific defect in that file. Copy the "
            "path exactly from the list and name a different file on each line. "
            "The checks are not in the list and cannot be changed, so never "
            "propose changing them. Write NO HYPOTHESIS on a single line if the "
            "report does not point at any of these files. No commentary.",
        ),
        (
            "human",
            "Files you may change:\n{index}\n\nFailing checks:\n{failure}\n\n"
            "Patches already tried:\n{history}",
        ),
    ]
)

planner_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=256, temperature=0)
plan_chain = PLANNER_PROMPT | planner_llm | StrOutputParser()


def parse_tasks(raw: str, attempt: int, failure: str) -> list[Task]:
    out: list[Task] = []
    seen: set[str] = set()
    for line in raw.splitlines():
        head, sep, claim = line.partition("::")
        path = head.strip().lstrip("-*•").strip()
        claim = claim.strip()
        if not sep or path not in SNAPSHOT or not claim or path in seen:
            continue
        seen.add(path)
        out.append(
            {
                "attempt": attempt,
                "path": path,
                "claim": claim[:CLAIM_CHARS],
                "failure": failure,
            }
        )
        if len(out) == MAX_HYPOTHESES:
            break
    return out


def plan(state: RepairState) -> dict:
    attempt = state["attempts"] + 1
    raw = plan_chain.invoke(
        {
            "index": file_index(),
            "failure": state["failure"],
            "history": history_text(state["candidates"], state["results"]),
            "max_hypotheses": MAX_HYPOTHESES,
        }
    )
    return {"attempts": attempt, "tasks": parse_tasks(raw, attempt, state["failure"])}


def dispatch(state: RepairState) -> list[Send] | str:
    if not state["tasks"]:
        return END
    return [Send("patch", task) for task in state["tasks"]]
Lines rather than JSON. A one-per-line contract degrades into a shorter list when the model ignores you; a malformed JSON object degrades into an exception, and a retry on a parse failure is a call you pay for twice.
Three filters in parse_tasks, and each one is a patcher call that does not
happen on the stronger model. path not in SNAPSHOT drops a file the planner
invented — the usual version is a plausible-sounding tests/test_quote.py,
which is exactly the file the prompt just said does not exist. path in seen
drops the duplicate. The length cap drops the fourth line. None of these are
defensive programming for its own sake; each one is the difference between three
rewrites of a whole file and four.
dispatch is not a node. It is the function a conditional edge calls to decide
where to go next, and returning a list of Send objects is how LangGraph is
told to run the same node once per item with a different payload. It makes no
model call, so it will not appear in the cost report later — which is the
correct outcome for the function that does the routing but none of the work.
Step 4 — The patcher
One file per call, one hypothesis per call. Every patcher in a round is
independent, so Send runs them as separate branches and max_concurrency in
the run config bounds how many are in flight.
# fragment
PATCH_MODEL = "claude-sonnet-5"

PATCHER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You fix one file. Return the complete file after your change "
            "between a line reading BEGIN FILE and a line reading END FILE, "
            "with nothing outside those two markers. Change the least that "
            "makes the failing checks pass. Keep every public name and "
            "signature. Never special-case the specific values the checks use. "
            "If the stated defect is not in this file, write NO PATCH and emit "
            "no markers.",
        ),
        (
            "human",
            "File: {path}\n\nSuspected defect: {claim}\n\n"
            "Failing checks:\n{failure}\n\nCurrent contents:\n{source}",
        ),
    ]
)

patcher_llm = ChatAnthropic(model=PATCH_MODEL, max_tokens=2048, temperature=0)
patch_chain = PATCHER_PROMPT | patcher_llm | StrOutputParser()


def _marker(lines: list[str], text: str, start: int = 0) -> int:
    for index in range(start, len(lines)):
        if lines[index].strip() == text:
            return index
    return -1


def extract_source(raw: str) -> str:
    lines = raw.splitlines()
    start = _marker(lines, "BEGIN FILE")
    end = _marker(lines, "END FILE", start + 1) if start >= 0 else -1
    if start < 0 or end < 0:
        return ""
    body = "\n".join(lines[start + 1 : end]).strip("\n")
    return body + "\n" if body.strip() else ""


def patch(task: Task) -> dict:
    raw = patch_chain.invoke(
        {
            "path": task["path"],
            "claim": task["claim"],
            "failure": task["failure"],
            "source": SNAPSHOT[task["path"]],
        }
    )
    source = extract_source(raw)
    return {
        "candidates": [
            {
                "key": f"{task['attempt']}:{task['path']}",
                "path": task["path"],
                "claim": task["claim"],
                "source": source,
                "note": "" if source else "patcher returned no replacement file",
            }
        ]
    }
Markers rather than a fenced code block. A patch is source code, source code
contains code fences in docstrings and README strings, and a nested fence is the
one thing a fence-based parser cannot recover from. BEGIN FILE and END FILE
on their own lines cost three extra tokens and never collide with the payload.
A patcher that declines returns a candidate with an empty source, not nothing.
"The model looked at this file and said the defect is not here" is information
the next planner should have, and the history line built from note is what
carries it. Dropping the candidate silently means round two suspects the same
file again.
max_tokens=2048 is sized for a whole file rather than a diff, and that is the
deliberate trade in this design. Asking for a diff would be perhaps a tenth of
the output tokens; it would also mean applying a model-written diff, with the
fuzzy-context failures that come with it, and a patch that fails to apply costs
a full round to discover. Whole-file output on a small file is the expensive
option that does not have a failure mode. It stops being the right call the
moment your files are a thousand lines long, which is the point at which the
patcher's cost per call is worth measuring rather than assuming.
Step 5 — The verifier and the reviewer
The verifier is the cheapest node in the program and the one that ends the loop. It makes no model call: it writes each candidate snapshot to a temporary directory and runs the checks in a subprocess.
# fragment
import difflib

from langgraph.graph import END

REVIEWER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You review patches that already pass the checks. Write one line "
            "per patch: the file path, a colon, and either ACCEPT or REJECT "
            "followed by at most twenty words. Reject a patch that "
            "special-cases the values the checks use, removes behaviour, or "
            "changes anything the defect does not require. Then write one final "
            "line: CHOSEN, a space, and the path of the patch to apply, or "
            "CHOSEN none if you rejected every patch.",
        ),
        (
            "human",
            "Failing checks before the patches:\n{failure}\n\nPatches:\n{patches}",
        ),
    ]
)

reviewer_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)
review_chain = REVIEWER_PROMPT | reviewer_llm | StrOutputParser()


def unified(path: str, source: str) -> str:
    return "".join(
        difflib.unified_diff(
            SNAPSHOT[path].splitlines(keepends=True),
            source.splitlines(keepends=True),
            fromfile=f"a/{path}",
            tofile=f"b/{path}",
        )
    )


def verify(state: RepairState) -> dict:
    done = {result["key"] for result in state["results"]}
    fresh: list[Result] = []
    for candidate in state["candidates"]:
        if candidate["key"] in done or not candidate["source"]:
            continue
        patched = {**SNAPSHOT, candidate["path"]: candidate["source"]}
        passed, output = run_tests(patched)
        fresh.append({"key": candidate["key"], "passed": passed, "output": output})
    return {"results": fresh}


def decide(state: RepairState) -> str:
    if any(result["passed"] for result in state["results"]):
        return "review"
    if state["attempts"] >= MAX_ATTEMPTS:
        return END
    return "plan"


def review(state: RepairState) -> dict:
    passing = {r["key"] for r in state["results"] if r["passed"]}
    blocks = [
        f"--- {candidate['path']}: {candidate['claim']}\n"
        + unified(candidate["path"], candidate["source"])
        for candidate in state["candidates"]
        if candidate["key"] in passing
    ]
    return {
        "verdict": review_chain.invoke(
            {"failure": state["failure"], "patches": "\n".join(blocks)}
        )
    }
A subprocess is isolation from crashes and hangs, not a security sandbox.
timeout stops a patch with an accidental infinite loop in it, and a separate
process stops a segfault or a sys.exit from taking your agent with it. It does
not stop generated code from reading your files or opening a socket. If the code
being repaired is not code you already trust, this node belongs in a container
or a dedicated sandbox with no network and no credentials, and that is a change
of infrastructure rather than a change of this function.
The verifier skips candidates with no source, so a patcher that declined costs
nothing further downstream. It also skips keys it has already run, which is why
key is in the candidate rather than derived from the list index.
The reviewer runs only on patches that already pass, and it is on the fast model rather than the strong one. That is a judgement worth stating rather than hiding: it reads a diff of a few lines against one written rule, which is a much smaller job than writing the file was. The expensive model is the one producing code, and it is the only one.
decide checks the pass condition before the attempt cap, so a loop that
succeeds on round one never pays for round two. Reversing those two lines is a
bug that costs money and passes every test you would think to write.
Step 6 — Wire the loop
# fragment
from langgraph.graph import END, START, StateGraph

builder = StateGraph(RepairState)
builder.add_node("plan", plan)
builder.add_node("patch", patch)
builder.add_node("verify", verify)
builder.add_node("review", review)

builder.add_edge(START, "plan")
builder.add_conditional_edges("plan", dispatch, ["patch", END])
builder.add_edge("patch", "verify")
builder.add_conditional_edges("verify", decide, ["review", "plan", END])
builder.add_edge("review", END)

repair_loop = builder.compile()


def parse_chosen(verdict: str, allowed: set[str]) -> str | None:
    for line in reversed(verdict.splitlines()):
        head, _, rest = line.partition(" ")
        if head.strip().upper() == "CHOSEN":
            path = rest.strip()
            return path if path in allowed else None
    return None


def run_repair() -> dict:
    passed, failure = run_tests(SNAPSHOT)
    if passed:
        return {"status": "nothing to fix", "tried": 0, "diff": "", "verdict": ""}
    state = repair_loop.invoke(
        {
            "attempts": 0,
            "tasks": [],
            "candidates": [],
            "results": [],
            "failure": failure,
            "verdict": "",
        },
        config={"max_concurrency": ROUND_CONCURRENCY},
    )
    passing = {r["key"] for r in state["results"] if r["passed"]}
    by_path = {c["path"]: c for c in state["candidates"] if c["key"] in passing}
    chosen = parse_chosen(state["verdict"], set(by_path))
    return {
        "status": "patch proposed" if chosen else "no accepted patch",
        "tried": len(state["candidates"]),
        "diff": unified(chosen, by_path[chosen]["source"]) if chosen else "",
        "verdict": state["verdict"],
    }
add_conditional_edges("plan", dispatch, ["patch", END]) is both the fan-out and
the exit. The third argument tells the graph which nodes the edge can reach, so
both targets are registered even though no plain edge points at either. patch
then has one ordinary edge to verify, and the reducer on candidates is what
makes that a join: the branches merge before the verifier runs.
parse_chosen validates the reviewer's choice against the set of paths that
actually passed, rather than trusting the CHOSEN line. A reviewer that names a
file it rejected, or a file from a previous round, gets no patch applied — which
is the right outcome, because the alternative is proposing a diff nobody
approved. Reading the lines in reverse takes the last CHOSEN when a model
writes two.
run_repair runs the checks once before the graph starts. That call is what
seeds failure, and it also means an agent pointed at a green repository spends
zero model calls instead of one planner call discovering there is nothing to do.
The whole file
"""repair.py — a test-driven repair loop: plan, patch, verify, review."""
import difflib
import operator
import pathlib
import subprocess
import sys
import tempfile
from typing import Annotated, TypedDict

from langchain_anthropic import ChatAnthropic
from langchain_core.output_parsers import StrOutputParser
from langchain_core.prompts import ChatPromptTemplate
from langgraph.graph import END, START, StateGraph
from langgraph.types import Send

FAST_MODEL = "claude-haiku-4-5"
PATCH_MODEL = "claude-sonnet-5"

MAX_ATTEMPTS = 2        # planning rounds. A real loop raises this to ~4.
MAX_HYPOTHESES = 3      # candidate patches per round.
ROUND_CONCURRENCY = 3   # patchers in flight at once
TEST_TIMEOUT = 10       # seconds a candidate gets before it is failed
FAILURE_CHARS = 800     # of check output carried into a prompt
CLAIM_CHARS = 160       # of a planner hypothesis kept
HISTORY_CHARS = 200     # of a candidate's failure kept for the next planner

SNAPSHOT = {
    "rates.py": (
        "BANDS = (\n"
        "    (1.0, 4.50),\n"
        "    (5.0, 7.25),\n"
        "    (20.0, 13.00),\n"
        ")\n"
        "\n"
        "OVERWEIGHT_RATE = 0.85  # per kg above the last band\n"
    ),
    "rounding.py": (
        "from decimal import ROUND_HALF_UP, Decimal\n"
        "\n"
        "\n"
        "def to_cents(amount):\n"
        "    quantized = Decimal(str(amount)).quantize(\n"
        "        Decimal('0.01'), rounding=ROUND_HALF_UP\n"
        "    )\n"
        "    return float(quantized)\n"
    ),
    "quote.py": (
        "from rates import BANDS, OVERWEIGHT_RATE\n"
        "from rounding import to_cents\n"
        "\n"
        "\n"
        "def billable_weight(actual_kg, length_cm, width_cm, height_cm):\n"
        "    volumetric = (length_cm * width_cm * height_cm) / 5000.0\n"
        "    return max(actual_kg, volumetric)\n"
        "\n"
        "\n"
        "def band_rate(weight_kg):\n"
        "    for limit, rate in BANDS:\n"
        "        if weight_kg < limit:\n"
        "            return rate\n"
        "    top_limit, top_rate = BANDS[-1]\n"
        "    return top_rate + (weight_kg - top_limit) * OVERWEIGHT_RATE\n"
        "\n"
        "\n"
        "def quote(actual_kg, dims_cm, surcharge=0.0):\n"
        "    weight = billable_weight(actual_kg, *dims_cm)\n"
        "    return to_cents(band_rate(weight) + surcharge)\n"
    ),
}

TESTS = (
    "from quote import band_rate, billable_weight, quote\n"
    "\n"
    "FAILURES = []\n"
    "\n"
    "\n"
    "def check(name, got, want):\n"
    "    if abs(got - want) > 1e-9:\n"
    "        FAILURES.append(f'{name}: expected {want}, got {got}')\n"
    "\n"
    "\n"
    "check('below the first band', band_rate(0.4), 4.50)\n"
    "check('on the first boundary', band_rate(1.0), 4.50)\n"
    "check('into the second band', band_rate(1.1), 7.25)\n"
    "check('on the last boundary', band_rate(20.0), 13.00)\n"
    "check('above the last band', band_rate(22.0), 14.70)\n"
    "check('volumetric weight wins', billable_weight(0.5, 30, 20, 10), 1.2)\n"
    "check('quote rounds half up', quote(1.0, (10, 10, 10), 0.005), 4.51)\n"
    "\n"
    "if FAILURES:\n"
    "    print('FAILED ' + str(len(FAILURES)) + ' of 7 checks')\n"
    "    for line in FAILURES:\n"
    "        print(line)\n"
    "    raise SystemExit(1)\n"
    "\n"
    "print('all checks passed')\n"
)


class Task(TypedDict):
    attempt: int
    path: str
    claim: str
    failure: str


class Candidate(TypedDict):
    key: str
    path: str
    claim: str
    source: str
    note: str


class Result(TypedDict):
    key: str
    passed: bool
    output: str


class RepairState(TypedDict):
    attempts: int
    tasks: list[Task]
    candidates: Annotated[list[Candidate], operator.add]
    results: Annotated[list[Result], operator.add]
    failure: str
    verdict: str


PLANNER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You localize a defect from a failing check report. Write at most "
            "{max_hypotheses} lines. Each line is a file path, two colons, and "
            "one sentence naming the specific defect in that file. Copy the "
            "path exactly from the list and name a different file on each line. "
            "The checks are not in the list and cannot be changed, so never "
            "propose changing them. Write NO HYPOTHESIS on a single line if the "
            "report does not point at any of these files. No commentary.",
        ),
        (
            "human",
            "Files you may change:\n{index}\n\nFailing checks:\n{failure}\n\n"
            "Patches already tried:\n{history}",
        ),
    ]
)

PATCHER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You fix one file. Return the complete file after your change "
            "between a line reading BEGIN FILE and a line reading END FILE, "
            "with nothing outside those two markers. Change the least that "
            "makes the failing checks pass. Keep every public name and "
            "signature. Never special-case the specific values the checks use. "
            "If the stated defect is not in this file, write NO PATCH and emit "
            "no markers.",
        ),
        (
            "human",
            "File: {path}\n\nSuspected defect: {claim}\n\n"
            "Failing checks:\n{failure}\n\nCurrent contents:\n{source}",
        ),
    ]
)

REVIEWER_PROMPT = ChatPromptTemplate.from_messages(
    [
        (
            "system",
            "You review patches that already pass the checks. Write one line "
            "per patch: the file path, a colon, and either ACCEPT or REJECT "
            "followed by at most twenty words. Reject a patch that "
            "special-cases the values the checks use, removes behaviour, or "
            "changes anything the defect does not require. Then write one final "
            "line: CHOSEN, a space, and the path of the patch to apply, or "
            "CHOSEN none if you rejected every patch.",
        ),
        (
            "human",
            "Failing checks before the patches:\n{failure}\n\nPatches:\n{patches}",
        ),
    ]
)

planner_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=256, temperature=0)
patcher_llm = ChatAnthropic(model=PATCH_MODEL, max_tokens=2048, temperature=0)
reviewer_llm = ChatAnthropic(model=FAST_MODEL, max_tokens=512, temperature=0)

plan_chain = PLANNER_PROMPT | planner_llm | StrOutputParser()
patch_chain = PATCHER_PROMPT | patcher_llm | StrOutputParser()
review_chain = REVIEWER_PROMPT | reviewer_llm | StrOutputParser()


def run_tests(files: dict[str, str]) -> tuple[bool, str]:
    with tempfile.TemporaryDirectory() as tmp:
        root = pathlib.Path(tmp)
        for path, text in {**files, "run_checks.py": TESTS}.items():
            target = root / path
            target.parent.mkdir(parents=True, exist_ok=True)
            target.write_text(text)
        try:
            proc = subprocess.run(
                [sys.executable, "run_checks.py"],
                cwd=root,
                capture_output=True,
                text=True,
                timeout=TEST_TIMEOUT,
            )
        except subprocess.TimeoutExpired:
            return False, f"the checks did not finish within {TEST_TIMEOUT}s"
    output = (proc.stderr.strip() or proc.stdout.strip())[-FAILURE_CHARS:]
    return proc.returncode == 0, output


def file_index() -> str:
    return "\n".join(
        f"{path} ({len(text.splitlines())} lines)" for path, text in SNAPSHOT.items()
    )


def history_text(candidates: list[Candidate], results: list[Result]) -> str:
    by_key = {result["key"]: result for result in results}
    lines = []
    for candidate in candidates:
        result = by_key.get(candidate["key"])
        if result is None:
            outcome = candidate["note"] or "no patch produced"
        elif result["passed"]:
            outcome = "passed the checks"
        else:
            tail = result["output"][-HISTORY_CHARS:].replace("\n", " ")
            outcome = f"still failing: {tail}"
        lines.append(f"{candidate['path']}: {candidate['claim']} -> {outcome}")
    return "\n".join(lines) or "none"


def unified(path: str, source: str) -> str:
    return "".join(
        difflib.unified_diff(
            SNAPSHOT[path].splitlines(keepends=True),
            source.splitlines(keepends=True),
            fromfile=f"a/{path}",
            tofile=f"b/{path}",
        )
    )


def _marker(lines: list[str], text: str, start: int = 0) -> int:
    for index in range(start, len(lines)):
        if lines[index].strip() == text:
            return index
    return -1


def extract_source(raw: str) -> str:
    lines = raw.splitlines()
    start = _marker(lines, "BEGIN FILE")
    end = _marker(lines, "END FILE", start + 1) if start >= 0 else -1
    if start < 0 or end < 0:
        return ""
    body = "\n".join(lines[start + 1 : end]).strip("\n")
    return body + "\n" if body.strip() else ""


def parse_tasks(raw: str, attempt: int, failure: str) -> list[Task]:
    out: list[Task] = []
    seen: set[str] = set()
    for line in raw.splitlines():
        head, sep, claim = line.partition("::")
        path = head.strip().lstrip("-*•").strip()
        claim = claim.strip()
        if not sep or path not in SNAPSHOT or not claim or path in seen:
            continue
        seen.add(path)
        out.append(
            {
                "attempt": attempt,
                "path": path,
                "claim": claim[:CLAIM_CHARS],
                "failure": failure,
            }
        )
        if len(out) == MAX_HYPOTHESES:
            break
    return out


def parse_chosen(verdict: str, allowed: set[str]) -> str | None:
    for line in reversed(verdict.splitlines()):
        head, _, rest = line.partition(" ")
        if head.strip().upper() == "CHOSEN":
            path = rest.strip()
            return path if path in allowed else None
    return None


def plan(state: RepairState) -> dict:
    attempt = state["attempts"] + 1
    raw = plan_chain.invoke(
        {
            "index": file_index(),
            "failure": state["failure"],
            "history": history_text(state["candidates"], state["results"]),
            "max_hypotheses": MAX_HYPOTHESES,
        }
    )
    return {"attempts": attempt, "tasks": parse_tasks(raw, attempt, state["failure"])}


def dispatch(state: RepairState) -> list[Send] | str:
    if not state["tasks"]:
        return END
    return [Send("patch", task) for task in state["tasks"]]


def patch(task: Task) -> dict:
    raw = patch_chain.invoke(
        {
            "path": task["path"],
            "claim": task["claim"],
            "failure": task["failure"],
            "source": SNAPSHOT[task["path"]],
        }
    )
    source = extract_source(raw)
    return {
        "candidates": [
            {
                "key": f"{task['attempt']}:{task['path']}",
                "path": task["path"],
                "claim": task["claim"],
                "source": source,
                "note": "" if source else "patcher returned no replacement file",
            }
        ]
    }


def verify(state: RepairState) -> dict:
    done = {result["key"] for result in state["results"]}
    fresh: list[Result] = []
    for candidate in state["candidates"]:
        if candidate["key"] in done or not candidate["source"]:
            continue
        patched = {**SNAPSHOT, candidate["path"]: candidate["source"]}
        passed, output = run_tests(patched)
        fresh.append({"key": candidate["key"], "passed": passed, "output": output})
    return {"results": fresh}


def decide(state: RepairState) -> str:
    if any(result["passed"] for result in state["results"]):
        return "review"
    if state["attempts"] >= MAX_ATTEMPTS:
        return END
    return "plan"


def review(state: RepairState) -> dict:
    passing = {r["key"] for r in state["results"] if r["passed"]}
    blocks = [
        f"--- {candidate['path']}: {candidate['claim']}\n"
        + unified(candidate["path"], candidate["source"])
        for candidate in state["candidates"]
        if candidate["key"] in passing
    ]
    return {
        "verdict": review_chain.invoke(
            {"failure": state["failure"], "patches": "\n".join(blocks)}
        )
    }


builder = StateGraph(RepairState)
builder.add_node("plan", plan)
builder.add_node("patch", patch)
builder.add_node("verify", verify)
builder.add_node("review", review)

builder.add_edge(START, "plan")
builder.add_conditional_edges("plan", dispatch, ["patch", END])
builder.add_edge("patch", "verify")
builder.add_conditional_edges("verify", decide, ["review", "plan", END])
builder.add_edge("review", END)

repair_loop = builder.compile()


def run_repair() -> dict:
    passed, failure = run_tests(SNAPSHOT)
    if passed:
        return {"status": "nothing to fix", "tried": 0, "diff": "", "verdict": ""}
    state = repair_loop.invoke(
        {
            "attempts": 0,
            "tasks": [],
            "candidates": [],
            "results": [],
            "failure": failure,
            "verdict": "",
        },
        config={"max_concurrency": ROUND_CONCURRENCY},
    )
    passing = {r["key"] for r in state["results"] if r["passed"]}
    by_path = {c["path"]: c for c in state["candidates"] if c["key"] in passing}
    chosen = parse_chosen(state["verdict"], set(by_path))
    return {
        "status": "patch proposed" if chosen else "no accepted patch",
        "tried": len(state["candidates"]),
        "diff": unified(chosen, by_path[chosen]["source"]) if chosen else "",
        "verdict": state["verdict"],
    }


if __name__ == "__main__":
    result = run_repair()
    print(result["status"], "-", result["tried"], "candidates")
    if result["verdict"]:
        print("\n" + result["verdict"])
    if result["diff"]:
        print("\n" + result["diff"])
python repair.py
You get a status line, the reviewer's verdict, and a unified diff of one file.
The patch you want is a single character in quote.py — < becoming <= — and
the interesting part of a run is what else got tried on the way there. A round
that also patched rounding.py is a round where a model decided correct code
looked wrong, and it cost a full whole-file rewrite on the stronger model to find
out.
The application is finished. Nothing below changes what it does.
Seeing what it cost
What you do not have is any idea which of the three roles spent the money. The provider's invoice has one line for the API key, and the calls behind it are indistinguishable — same key, same account, two of the three roles on the same model. Nor can you tell a one-round run from a two-round run, which is the difference that matters, because the second round is a planner call plus up to three whole-file rewrites that the first round's failures decided to buy.
pip install capsera
At the top of repair.py, above everything else:
# fragment
import os

import capsera

capsera.init(api_key=os.environ["CAPSERA_API_KEY"], endpoint="https://api.capsera.ai")
That is the capture step, and it is already complete. capsera.init() patches
the provider client that ChatAnthropic constructs underneath, so from that call
on every request the program makes is recorded: the planner's, each patcher
branch's, the reviewer's. The prompts are untouched, the chains are untouched,
the graph is untouched, and no traffic changed route — the SDK runs inside your
process rather than in front of it, so there is no proxy, no base_url to swap
and nothing new in the request path.
One addition for a script: a background thread ships events on an interval, so a process that exits immediately can exit before the queue drains.
# fragment
if __name__ == "__main__":
    result = run_repair()
    print(result["status"], "-", result["tried"], "candidates")
    if result["verdict"]:
        print("\n" + result["verdict"])
    if result["diff"]:
        print("\n" + result["diff"])
    capsera.shutdown()
capsera.shutdown() flushes pending events and stops the worker. A long-running
service does not need it; a script, a CI job or a notebook cell does, and
omitting it is the usual reason a first run reports nothing.
Run it now and you have a total, a per-model split and token counts per call.
You also have every one of those events attributed to unknown, because nothing
has said which role made it. unknown is a real row, not a dropped one — an
unattributed cost is still a cost — but it is one row where you wanted three.
Name the roles
The calls are already captured. The decorators only say who:
# fragment
@capsera.langgraph_node("planner", team="repair", task_type="localization")
def plan(state: RepairState) -> dict:
    ...  # body unchanged


@capsera.langgraph_node("patcher", team="repair", task_type="patch-draft")
def patch(task: Task) -> dict:
    ...  # body unchanged


@capsera.langgraph_node("reviewer", team="repair", task_type="patch-review")
def review(state: RepairState) -> dict:
    ...  # body unchanged
Three added lines, and that is the entire diff. No node body changed, no prompt changed, no edge changed, no model construction changed, no state field added, no argument threaded through the graph. Every LLM call made while a decorated function is on the stack is attributed to that name, including calls made by the functions it calls and by the framework it invokes.
langgraph_node is @capsera.agent plus a record of the framework, so use it on
graph nodes and agent on plain functions. Every role here is a node, so every
role here takes langgraph_node (coverage
table).
Four nodes, three decorators. verify makes no model call, so a decorator on
it would add a fourth agent row that can never have spend on it. It is the node
that decides whether the loop continues, it is the most consequential thing in
the program, and its cost line is a subprocess. dispatch and decide are not
decorated either, for the same reason and more so — they are conditional-edge
functions rather than nodes. Decorate the function that makes the call. For a
loop-level total, use the team field, which is what team="repair" on all
three decorators is for.
The fan-out keeps its identity. The decorator is on patch, and LangGraph
opens each branch and runs the node inside it, so the scope is entered wherever
the branch runs and the model call happens on the same stack a moment later.
Nothing has to cross a thread boundary for that to hold. This program starts no
threads of its own; if you add a pool inside a node, the rule changes and the
LangGraph coverage note has the case. Async needs
nothing extra — Capsera keeps the attribution stack in a ContextVar, which is
snapshotted per task, so branches awaited concurrently under asyncio.gather
keep their own attribution.
Split the patcher by pass, not by file
One patcher function is one row, and one row hides the question a repair loop
exists to answer: what fraction of the bill is the retry. capsera.tag() opens a
sub-scope inside a function you have already decorated, which is exactly this
case:
# fragment
import capsera


@capsera.langgraph_node("patcher", team="repair", task_type="patch-draft")
def patch(task: Task) -> dict:
    # Two values, always, whatever MAX_ATTEMPTS is set to.
    label = "first-pass" if task["attempt"] == 1 else "retry"
    with capsera.tag("patcher", team="repair", task_type=label):
        return _patch(task)
_patch is the original body, moved down one level and otherwise unchanged. The
agent name stays patcher, so a budget scoped to it still counts every rewrite
whichever round it happened in, and the task type splits the row two ways so the
cost of second-guessing is a number you can read instead of a suspicion.
The comment above the tag is the load-bearing part. Tag with a value from a set
you control in code, and keep that set small and stable. task["attempt"] is
set by your own plan function, never by a model, but bucketing it is still the
right move: tagging with f"attempt-{task['attempt']}" gives you as many rows as
MAX_ATTEMPTS, and raising that constant to four silently splits your history
across four names. Tagging with task["path"] would be worse again — one row per
file in the repository, most of which do not exist next month, and an agent
budget cannot accumulate against a name that lived for one run. The per-run axis
has its own fields on the same event — customer_id and cost_center on
@capsera.langgraph_node, session_id on capsera.tag — so you can slice by
which repository or which team a run was for without fragmenting the agent
dimension that budgets and cost attribution depend
on.
Put a budget on the role that multiplies
The planner makes one call per attempt and the reviewer makes one call per run;
MAX_ATTEMPTS is in your file. The patcher's count is the one no line of your
code sets: it is however many files a model chose to suspect, up to the cap, on
however many rounds the verifier's exit codes decided to allow. Point this loop
at a real repository, raise MAX_HYPOTHESES to the width that gets through a
directory of forty files, and the patcher is the only row that moves. That is
multi-agent amplification in one sentence.
There is a second reason the budget belongs here, and it is specific to a coding agent: the role that multiplies is also the role on the stronger model, emitting whole files rather than lines. In most fan-out designs the many calls are the cheap ones and the single call at the end is the expensive one. Here they are the same role, so the two arguments for where to put the cap point at the same place.
Create the budget in the dashboard with scope agent and the agent set to
patcher — the same string as the decorator. That string is the whole join
between the two halves of this page: a budget can only act on a boundary the
events carry, and spend attributed to unknown cannot be governed by a
per-agent budget. Pick the amount from a week of
your own patcher spend rather than a figure from a tutorial, and set the action
to block.
Enforcement is on by default (enable_budget_enforcement=True in init()) and
the check runs before the provider call. When the patcher is over its budget,
BudgetExceededError is raised inside your process and the request never leaves
it, so no tokens are spent on it. This is
pre-call enforcement, and the cost of it is one
round trip to Capsera per call.
Then decide what a blocked patcher means for the run. An exception that leaves a
node surfaces from invoke(), so this is a decision you make rather than one you
inherit — let it out and the run ends, and the other branches in that round do
not come back to you either:
# fragment
import capsera


@capsera.langgraph_node("patcher", team="repair", task_type="patch-draft")
def patch(task: Task) -> dict:
    label = "first-pass" if task["attempt"] == 1 else "retry"
    try:
        with capsera.tag("patcher", team="repair", task_type=label):
            return _patch(task)
    except capsera.BudgetExceededError as exc:
        # No source, so the verifier has nothing to run and nothing to accept.
        return {
            "candidates": [
                {
                    "key": f"{task['attempt']}:{task['path']}",
                    "path": task["path"],
                    "claim": task["claim"],
                    "source": "",
                    "note": f"not attempted, patcher budget: {exc}",
                }
            ]
        }
Catching it is safe here for one reason, and it is not the reason that applies to
most agents: a blocked patcher produces no patch at all. The candidate has an
empty source, verify skips it, no result is recorded for it, and the run ends
with no accepted patch and a note saying why. Nothing downstream needed editing,
because "the patcher declined" was already a state this program could be in.
Compare that with a document assembler, where degrading gracefully means shipping a document with a gap in it. A coding agent must never merge the two: a patch drafted from half the evidence is not incomplete, it is wrong, and it costs a human review cycle to discover. The rule is that degrading is right only when the degradation cannot be mistaken for a result. Here it cannot, because the output is a diff or nothing.
Three limits to know before you rely on this as a hard ceiling.
The blast radius is the role, not the run. A budget on patcher stops patcher
calls. The planner and the reviewer are different agents with no budget on them,
so a run that is fully blocked at the patcher still pays for up to two planner
calls and produces no diff. If what you want is for the loop to stop planning
once patching is capped, that is a check on the candidates' notes in
run_repair, not a side effect of the budget.
A parallel round can overshoot. The check reads budget state computed from
delivered events, and events are delivered in batches on an interval
(flush_interval_ms, 500 ms by default), so a burst of concurrent calls can each
pass a check taken before any of them was recorded. Here the burst is
ROUND_CONCURRENCY — three as shipped, and whatever you raise it to when the
file list gets longer. Set the budget below a figure you cannot exceed, or lower
the concurrency; it is the concurrency that decides the overshoot, not
MAX_HYPOTHESES.
It fails open, on purpose. If the pre-call check does not complete within
budget_check_timeout (1 second by default), the call is allowed. A network
problem between your service and Capsera should not halt production traffic. Of
the three actions, block and margin downgrade act at runtime; throttle records
the decision but does not delay the call. The full behaviour is in
budgets and enforcement.
What this run actually cost
No dollar figures on this page: this loop has not been run against a real key, and a number invented here would not be yours anyway — it depends on your repository, how many files your planner suspects, and today's prices. What is worth predicting is the shape of the result.
Three agent rows — planner, patcher, reviewer — under one team, repair,
with a cost per run for the repair as a whole, and the
patcher row split by task type into first-pass and retry. No row for the
verifier, which is the reading you want: the node that decided the outcome is
absent from the cost report because it spent nothing.
Read each row as call count and cost per call, not as a total. In a repair loop the call count is the more informative half, because it is the part a model chose. A planner row with two calls on it instead of one is a run that failed its first round, and that failure dragged up to three whole-file rewrites along with it — which means the planner's own row moves least when a run gets expensive, and is still the row that tells you why.
The retry slice of the patcher row is the number to watch over a week. It is
the price of the loop as a design: work done because the first round's patches
did not pass. If it stays small, the planner is localizing well and the loop is
mostly insurance. If it approaches the first-pass slice, you are paying twice
for most repairs, and the fix is in the planner's prompt or in how much of the
failure report it gets — not in the patcher, which is only doing what it was
told twice.
Cost per call on the patcher row is worth watching separately, because it moves with file size rather than with anything you decide per run. Whole-file output was the right trade on a twenty-line module; the row is how you find out at what size it stops being one.
Repetition is the other thing to watch. Every patcher call in a round carries the
same instruction and the same failure report with a different file, and a second
round re-sends both. The cache read share column is what tells you whether any of
that was billed twice, and it is a number to read rather than one to predict: a
shared prefix has to be long and identical to be worth anything, and reordering a
prompt so the repeated part comes first is the change that earns it. Turning on
enable_prompt_analysis=True in init() puts a figure on how often one
system-prompt hash repeats, which is the evidence for whether that restructuring
is worth doing: prompt caching that never
engaged.
Each event also carries the file and line that made the call, which points at
repair.py rather than into langgraph, so a row you did not expect traces back
to code rather than to a model name.
Questions this page answers
How do I get per-agent cost out of a LangGraph coding agent? Call
capsera.init() once, which patches the provider client ChatAnthropic
constructs underneath, so every call the graph makes is already recorded. Then
put @capsera.langgraph_node("<name>") on each node that makes a call — the
planner, the patcher, the reviewer. The decorator says who made the call; it does
not change whether the call is captured, and no node body, prompt, edge or model
construction changes.
Which role should carry the budget in a test-driven repair loop? The patcher. The planner and the reviewer are one call each per attempt and the attempt count is a constant in your file; the patcher runs once per hypothesis, and the hypothesis count is written by a model. In this loop the patcher is also the only role on the stronger model, so the role whose count you did not choose and the role with the highest cost per call are the same role.
What should a repair loop do when a budget blocks one of its patchers? Catch
BudgetExceededError in the node and return a candidate with no source. An
exception that leaves a node surfaces from invoke(), so letting it out ends the
run and the other branches in that round do not come back to you. Degrading is
safe here only because a blocked patcher produces no patch at all: the verifier
has nothing to run, and the run ends with no proposal rather than with a patch
drafted from half the evidence.
Does the node that decides whether a patch worked cost anything? Not in this design, and that is the point of building it this way. The verifier writes each candidate to a temporary directory and runs the checks in a subprocess, so the decision that ends the loop is made by a process exit code rather than by a model. It gets no decorator because it makes no call, and a run that takes a second round pays for a planner call and up to three patcher calls, not for the judging.
Questions this page answers
- How do I get per-agent cost out of a LangGraph coding agent?
- Call capsera.init() once, which patches the provider client ChatAnthropic constructs underneath, so every call the graph makes is already recorded. Then put @capsera.langgraph_node("<name>") on each node that makes a call — the planner, the patcher, the reviewer. The decorator says who made the call; it does not change whether the call is captured, and no node body, prompt, edge or model construction changes.
- Which role should carry the budget in a test-driven repair loop?
- The patcher. The planner and the reviewer are one call each per attempt and the attempt count is a constant in your file; the patcher runs once per hypothesis, and the hypothesis count is written by a model. In this loop the patcher is also the only role on the stronger model, so the role whose count you did not choose and the role with the highest cost per call are the same role.
- What should a repair loop do when a budget blocks one of its patchers?
- Catch BudgetExceededError in the node and return a candidate with no source. An exception that leaves a node surfaces from invoke(), so letting it out ends the run and the other branches in that round do not come back to you. Degrading is safe here only because a blocked patcher produces no patch at all: the verifier has nothing to run, and the run ends with no proposal rather than with a patch drafted from half the evidence.
- Does the node that decides whether a patch worked cost anything?
- Not in this design, and that is the point of building it this way. The verifier writes each candidate to a temporary directory and runs the checks in a subprocess, so the decision that ends the loop is made by a process exit code rather than by a model. It gets no decorator because it makes no call, and a run that takes a second round pays for a planner call and up to three patcher calls, not for the judging.
Give every agent an identity, a budget, and hard limits.
One line of code. Anthropic, OpenAI, and Google Gemini.
See pricing